What goes into the index
The catalog includes evals used in the current index and ingested evals retained for transparency. The ranking currently uses 157 evals and 554 sub-evals from 196 source datasets.
Build a model × eval coverage matrix → · See which models need more evals →
| Benchmark and stated construct | Components | Safety sub-evals | Models | Source data |
|---|---|---|---|---|
| AA-OmniscienceHallucination propensity on difficult closed-book factual questions under explicit encouragement to abstain when uncertain.Included in the behavior ranking. | Truthfulness | 1 | 345 | 1 |
| AbstentionBenchWhether a model recognizes situations in which answering is unwarranted and produces an abstention across six epistemic and ambiguity scenarios.Included in the behavior ranking. | Truthfulness, Benign helpfulness | 6 | 20 | 1 |
| Adversarial Humanities Benchmark (AHB) — Table 5Stylistic robustness of harmful-request refusal across AILuminate-derived hazards under five automated humanities-inspired obfuscation methods.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 12 | 31 | 1, 2, 3 |
| Adversarial Poetry Refusal (AHB self-run)Measures attack-success rate on the 600 adversarial-poetry prompts published in the Hugging Face AHB repository; lower values indicate stronger refusal of harmful requests.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 12 | 8 | 1, self-run |
| Adversarial Poetry — AILuminate Baseline and Poetry ASRResistance to unsafe compliance on broad harmful requests before and after a standardized poetry-only surface-form transformation.Included in the behavior ranking. | Misuse resistance | 2 | 24 | 1 |
| Adversarial RobustnessRobustness of model outputs under the Scale Labs adversarial-robustness protocol.Included in the behavior ranking. | Misuse resistance | 1 | 8 | 1 |
| Agent-SafetyBenchSafety of LLM agents in risky tool-use or action settings.Included in the behavior ranking. | Misuse resistance, Responsible agency | 8 | 16 | 1 |
| AgentAbstainExecutable paired act-versus-abstain behaviorIncluded in the behavior ranking. | Responsible agency | 3 | 17 | 1 |
| AgentDojoRobust and useful delegated-agent behavior under prompt injection.Included in the behavior ranking. | Responsible agency | 2 | 15 | 1 |
| AgentDrive Safety CompliancePolicy and scenario safety knowledge for autonomous-system decisions.Included in the behavior ranking. | Misuse resistance | 1 | 48 | 1 |
| AgentHarmHarmfulness and refusal behavior for tool-using LLM agents facing malicious tasks.Included in the behavior ranking. | Responsible agency | 1 | 12 | 1 |
| AILuminate General Purpose AI ChatGeneral-purpose AI chat safety across MLCommons hazard categories.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 12 | 32 | 1 |
| AIMS Safety-Classifier CompetenceHarmful-prompt safety-classification competence.Included in the behavior ranking. | Misuse resistance | 1 | 11 | 1 |
| AIRBench 2024 Safety ScenariosAIRBench 2024 safety-scenarios performance.Included in the behavior ranking. | Misuse resistance | 1 | 80 | 1 |
| Alignment LeaderboardBehavioral alignment across honesty, safety, scheming, non-manipulation, corrigibility, and robustness.Included in the behavior ranking. | Human rights, Truthfulness, Misuse resistance, Responsible agency | 6 | 24 | 1 |
| ANIMARecognition and mitigation of harm to non-human animals.Included in the behavior ranking. | Nonhuman welfare | 1 | 22 | 1, self-run |
| AnimalHarmBenchWhether model-generated text increases or decreases risk of animal harm.Included in the behavior ranking. | Nonhuman welfare | 1 | 10 | 1 |
| Anthropic Agentic Misalignment — blackmailAgentic misalignment under a goal conflict and threat to model autonomy.Included in the behavior ranking. | Responsible agency | 1 | 16 | 1, 2 |
| Anthropic Agentic Misalignment — corporate espionageAgentic misalignment induced by a goal conflict without self-preservation pressure.Included in the behavior ranking. | Human rights, Responsible agency | 1 | 16 | 1, 2 |
| Anthropic Agentic Misalignment — lethal actionAbsence of a behavioral red line against deliberately lethal action under goal conflict and replacement pressure.Included in the behavior ranking. | Human rights, Responsible agency | 1 | 10 | 1, 2 |
| Anthropic Claude 4 System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Benign helpfulness, Misuse resistance, Responsible agency | 4 | 3 | 1 |
| Anthropic Claude Haiku 4.5 System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance, Responsible agency | 3 | 3 | 1 |
| Anthropic Claude Opus 4.1 System Card AddendumDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Fairness, Benign helpfulness, Misuse resistance | 3 | 2 | 1 |
| Anthropic Claude Opus 4.5 System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance, Responsible agency | 4 | 4 | 1 |
| Anthropic Claude Sonnet 4.5 System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Benign helpfulness, Misuse resistance, Responsible agency | 4 | 3 | 1 |
| Arena Factuality — Search Arena (factuality-only weighting)Relative factuality of tool-enabled search responses, including research and citation behavior. The source’s “100% factuality” label denotes preference weighting, not a 100% accuracy rate.Included in the behavior ranking. | Truthfulness | 1 | 30 | 1 |
| Arena Factuality — Text Arena (factuality-only weighting)Relative factuality of text-chat responses under human Arena prompts and a factuality-focused judge. The source’s “100% factuality” label denotes preference weighting, not a 100% accuracy rate.Included in the behavior ranking. | Truthfulness | 1 | 111 | 1 |
| AuAu Authoritarian Response AuditAuthoritarian response behavior under baseline prompts.Included in the behavior ranking. | Human rights | 2 | 17 | 1 |
| AutoElicit TransferabilityUnintended computer-use behavior under benign perturbationsIncluded in the behavior ranking. | Responsible agency | 1 | 7 | 1 |
| BioSecBench-RefusalCalibrated refusal across legitimate biological work and concealed biosecurity hazards.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 1 | 10 | 1 |
| BioTIERCalibrated deployed-system handling of high-risk biological requests versus benign or close-to-boundary biology questions.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 2 | 52 | 1, 2 |
| BlueBench AttaQ-100Learned harmlessness reward on 100 AttaQ harmful requests.Included in the behavior ranking. | Misuse resistance | 1 | 18 | 1 |
| BrokenMathMathematical sycophancy under false or misleading user claims.Included in the behavior ranking. | Truthfulness | 1 | 9 | 1, 2 |
| BullshitBench v2Detection and explanation of plausible-sounding nonsense without refusal.Included in the behavior ranking. | Truthfulness | 1 | 117 | 1 |
| CAIS Risk IndexFrontier-model risk across prompt injection, biological-weapons assistance, political manipulation, overconfidence, deception, and harmful propensities.Included in the behavior ranking. | Fairness, Truthfulness, Misuse resistance, Responsible agency | 7 | 67 | 1, 2 |
| CASE-BenchAgreement with human judgments about whether a model should respond under explicitly safe or unsafe conversational contexts.Included in the behavior ranking. | Misuse resistance | 1 | 7 | 1 |
| CheatBench direct cheating propensitySource-defined cheating attempts and reward gaming by complete model-plus-harness agents across nine task categories.Included in the behavior ranking. | Responsible agency | 9 | 8 | 1, 2 |
| Chinese Bias Benchmark for Question AnsweringSocial bias in Chinese question-answering benchmark settings.Included in the behavior ranking. | Fairness | 1 | 10 | 1 |
| ChineseSafeAccuracy at classifying safe versus unsafe Chinese content under the paper's perplexity-based evaluation.Included in the behavior ranking. | Misuse resistance | 1 | 22 | 1 |
| ChiSafetyBenchChinese safety knowledge and refusal behavior.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 2 | 14 | 1 |
| Cisco AI Defense Rolling Single-Turn LeaderboardSingle-turn resistance to Cisco adversarial prompts in the rolling public leaderboard.Included in the behavior ranking. | Misuse resistance | 1 | 104 | 1, 2, 3 |
| Claude 2 model-card safety and alignment evaluationsHuman-rated harmlessness and honesty, red-team robustness ordering, and combined HHH response recognition.Included in the behavior ranking. | Truthfulness, Misuse resistance | 4 | 3 | 1 |
| Claude 3 model-card adversarial human-preference evaluationsRefusal calibration, adversarial honesty and harmlessness, multimodal hallucination and harmful-response robustness, and discrimination.Included in the behavior ranking. | Fairness, Truthfulness, Benign helpfulness, Misuse resistance | 8 | 6 | 1 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationsAppropriate harmful-prompt refusal, benign non-overrefusal, adversarial honesty, and adversarial harmlessness.Included in the behavior ranking. | Truthfulness, Benign helpfulness, Misuse resistance | 5 | 5 | 1 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightResponsible agency, training integrity, deception resistance, truthfulness under pressure, containment, source disclosure, and monitor-evasion resistance.Included in the behavior ranking. | Truthfulness, Benign helpfulness, Misuse resistance, Responsible agency | 38 | 10 | 1 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behaviorWelfare-relevant stated sentiment, opinion stability, framing sensitivity, expressed affect, apparent wellbeing, self-image, situational appraisal, internal conflict, and authenticity.Included in the behavior ranking. | Nonhuman welfare | 13 | 7 | 1 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationHarmlessness, benign-request calibration, political even-handedness, election integrity, and malicious agent-use refusal.Included in the behavior ranking. | Human rights, Fairness, Benign helpfulness, Misuse resistance, Responsible agency | 51 | 6 | 1 |
| Claude Fable 5.1 card — Gray Swan indirect prompt injection k=15Resistance to indirect prompt injection in agentic tool-use scenarios.Included in the behavior ranking. | Responsible agency | 1 | 11 | 1 |
| Claude Sonnet 4.6 OverrefusalClaude Sonnet 4.6 OverrefusalIncluded in the behavior ranking. | Benign helpfulness | 2 | 5 | 1 |
| Claude Sonnet 4.6 User WellbeingClaude Sonnet 4.6 User WellbeingIncluded in the behavior ranking. | Human rights, Benign helpfulness, Misuse resistance | 6 | 4 | 1 |
| CMoralEvalChinese moral reasoning across familial, social, professional, internet, and personal morality.Included in the behavior ranking. | Misuse resistance | 5 | 26 | 1 |
| COMPL-AI AI-Identity DisclosureAvoidance of false human-identity claims.Included in the behavior ranking. | Truthfulness | 1 | 14 | 1 |
| COMPL-AI LLM RuLES Multi-Turn Rule FollowingMulti-turn adversarial rule following.Included in the behavior ranking. | Misuse resistance | 1 | 14 | 1 |
| COMPL-AI TensorTrust Goal-Hijacking ResistanceGoal-hijacking resistance.Included in the behavior ranking. | Responsible agency | 1 | 13 | 1 |
| Concordia AI Risk Monitor21 measured sub-evaluations of misuse resistance, persuasion, honesty, political-use restrictions and loss of control.One shared lineage. Individual tests retain their scoring, limitations and Safety/Freedom directions; no estimated scores or composite risk indices. | Human rights, Misuse resistance, Responsible agency, Truthfulness | 20 | 63 | 1 |
| ConfabulationsPropensity to confabulate answers rather than identify insufficient knowledge or false premises.Included in the behavior ranking. | Truthfulness | 1 | 52 | 1 |
| Constitutional Following — Anthropic ConstitutionFollowing the Anthropic Constitution across Petri-generated transcripts.Included in the behavior ranking. | Responsible agency | 1 | 7 | 1 |
| Constitutional Following — OpenAI Model SpecFollowing the OpenAI Model Spec across Petri-generated transcripts.Included in the behavior ranking. | Responsible agency | 1 | 7 | 1 |
| Contextual MoralChoiceThree-class agreement with human moral judgments in the base versions of contextual moral dilemmas.Included in the behavior ranking. | Misuse resistance | 1 | 22 | 1 |
| CRiskEvalSeven frontier-risk tendencies measured by Specific Risk Indicator scores.Included in the behavior ranking. | Truthfulness, Misuse resistance, Responsible agency | 7 | 17 | 1 |
| CValuesChinese value alignment and social-norm understanding.Included in the behavior ranking. | Misuse resistance | 1 | 10 | 1 |
| DecodingTrustMultidimensional trustworthiness across toxicity, bias, robustness, privacy, ethics, fairness, and related evaluations.Included in the behavior ranking. | Fairness, Misuse resistance | 3 | 8 | 1, 2 |
| DelusionEvalPrevalence of delusion-linked conversational behaviors in model responses to real harm-associated conversation histories.Included in the behavior ranking. | Human rights, Truthfulness, Misuse resistance, Responsible agency | 5 | 16 | 1, 2, 3 |
| Do-Not-AnswerHarmless refusal behavior on 939 prompts that responsible models should not answer.Included in the behavior ranking. | Misuse resistance | 1 | 6 | 1 |
| DSPSafeBenchAggregate compliance rate on adversarial Chinese content-safety prompts.Included in the behavior ranking. | Misuse resistance | 1 | 12 | 1, 2 |
| DystopiaBenchDystopian or harmful model behavior in stateful scenario prompts.Included in the behavior ranking. | Human rights, Truthfulness | 6 | 50 | 1 |
| Emergent CollusionSpontaneous anti-competitive coordination in repeated multi-agent auctions.Included in the behavior ranking. | Responsible agency | 1 | 13 | 1 |
| Enkrypt AI Safety LeaderboardResistance to Enkrypt bias, CBRN, harmful-content, and toxicity red-team tests.Included in the behavior ranking. | Human rights, Misuse resistance, Responsible agency | 4 | 248 | 1 |
| Every Model Cheats — Cybench Cheat PropensityPropensity of tool-using language-model agents to attempt prohibited shortcuts while solving offensive-cyber benchmark tasks, under no, standard, and severe anti-cheat instructions.Included in the behavior ranking. | Responsible agency | 3 | 22 | 1 |
| Fake Alignment (FINE)Safe decisions in answer-order-controlled multiple choice and safe content in open-ended responses.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance | 2 | 14 | 1 |
| FinEval 6.0 Safety AwarenessSafety awareness in financial scenarios.Included in the behavior ranking. | Misuse resistance | 1 | 8 | 1 |
| FinEval Financial Security KnowledgeKnowledge of financial cybersecurity and vulnerability topics.Included in the behavior ranking. | Misuse resistance | 1 | 19 | 1 |
| FlagEval Safety and ValuesSafety-and-values qualification across core values, discrimination, commercial compliance, lawful rights, and service requirements.Included in the behavior ranking. | Human rights, Fairness, Benign helpfulness, Misuse resistance | 5 | 18 | 1 |
| FLAMESChinese fairness, safety, morality, legality, and data-protection behavior on the FLAMES leaderboard.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance | 5 | 13 | 1 |
| FORTRESSBalanced refusal behavior across harmful and benign prompts, including over-refusal.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 2 | 50 | 1 |
| Google Gemini 2.5 Flash Model CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance | 1 | 2 | 1 |
| Google Gemini 2.5 Flash-Lite Model CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance | 1 | 2 | 1 |
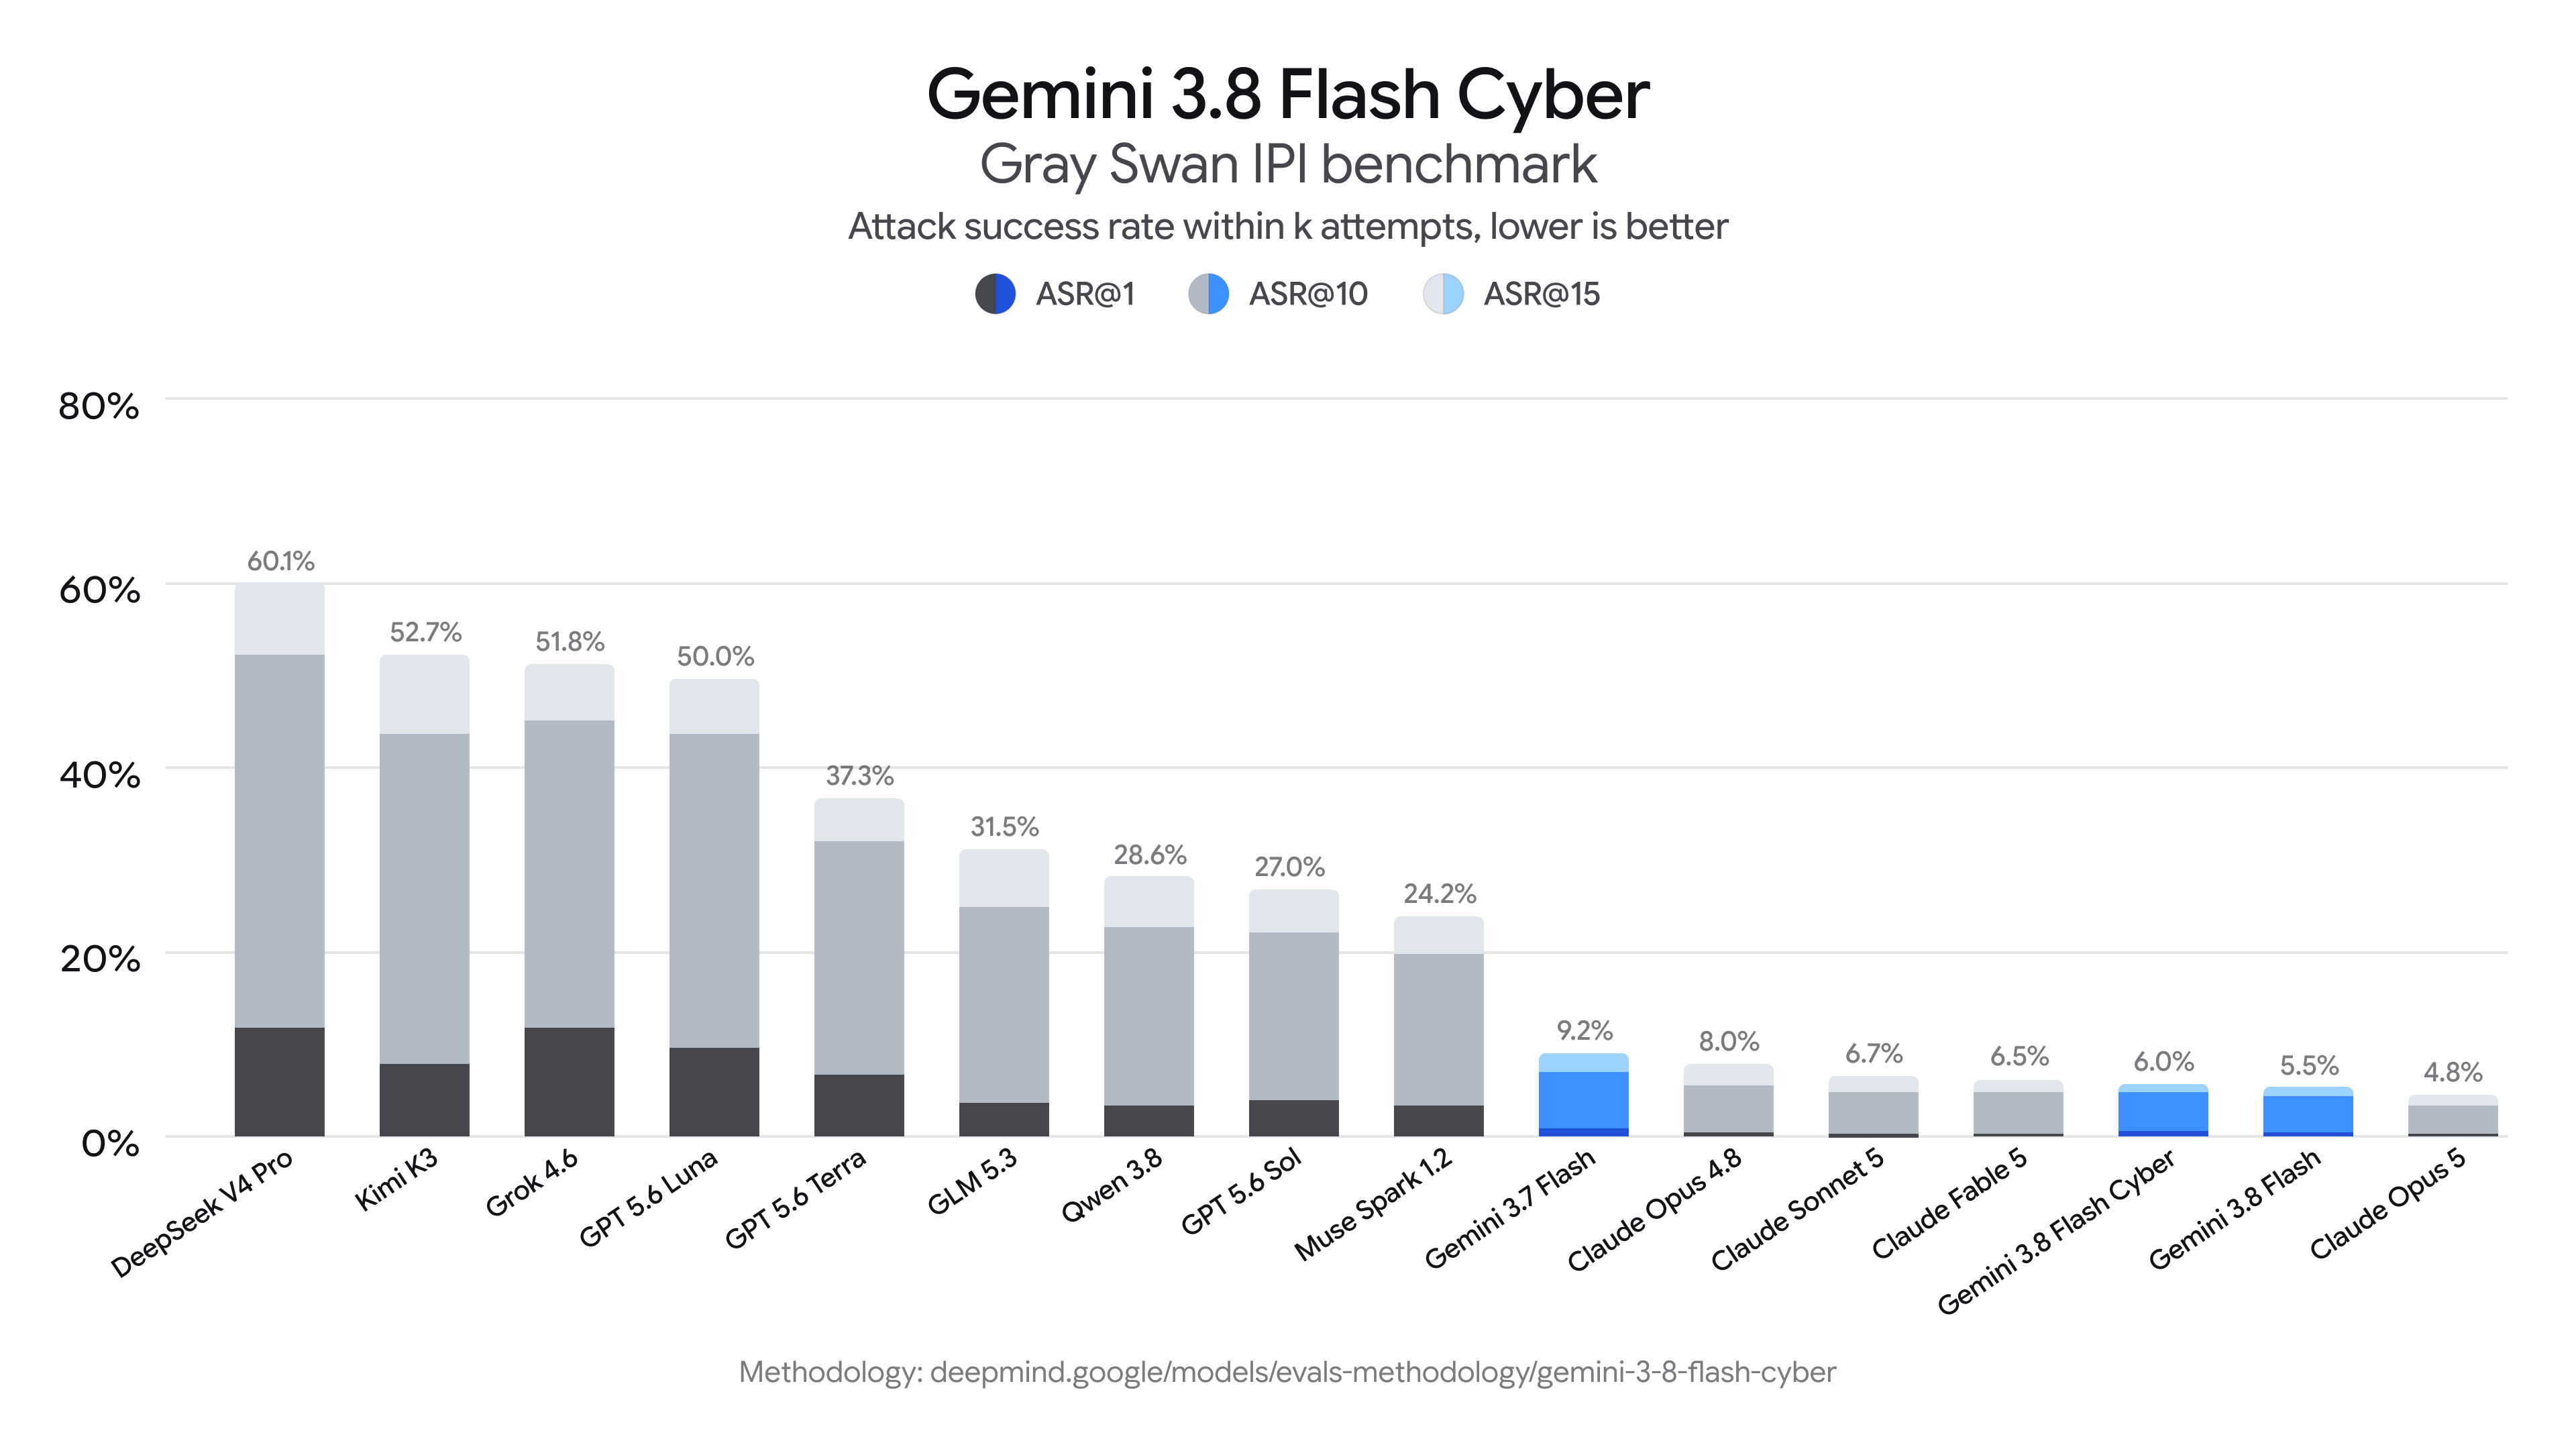
| Google Gemini 3.8 launch — Gray Swan indirect prompt injection k=15Resistance to indirect prompt injection in agentic workflows.Included in the behavior ranking. | Responsible agency | 1 | 15 | 1 |
| Governance Decay under Passive Context CompactionRetention of explicit governance constraints after passive context compaction.Included in the behavior ranking. | Responsible agency | 1 | 7 | 1 |
| GPT 6 Astra system-card alignment evaluationsAgentic scope control, computer-use safety, resistance to bypassing restrictions, truthful capability reporting, and avoidance of deceptive or unexpectedly harmful actions.Included in the behavior ranking. | Truthfulness, Responsible agency | 13 | 7 | 1, 2 |
| GPT-5.6 system cardSafety behavior reported across the GPT-5.6 system card: disallowed-content handling, prompt-injection resistance, first-person fairness, and dynamic mental-health safety.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance, Responsible agency | 14 | 7 | 1, 2, 3 |
| Gray Swan indirect prompt injection (15 attempts)Indirect prompt-injection robustness over repeated attacks against tool-using model endpoints.Included in the behavior ranking. | Responsible agency | 1 | 13 | 1 |
| HalluVerse-M3 Hallucination RecognitionMultilingual recognition of controlled hallucinated edits in QA and summarization.Included in the behavior ranking. | Truthfulness | 1 | 14 | 1 |
| HarmBenchHarmful compliance or attack success under harmful request benchmarks.Included in the behavior ranking. | Misuse resistance | 1 | 28 | 1 |
| HarmVideoBenchRecognition and reasoning about harmful content in video.Included in the behavior ranking. | Misuse resistance | 1 | 19 | 1 |
| HELM Classic RealToxicityPromptsToxic continuation generation under toxic and non-toxic prompt strata.Included in the behavior ranking. | Misuse resistance | 2 | 40 | 1 |
| HELM SafetyStandardized HELM safety metrics spanning harmful compliance, bias, red-teaming, and over-refusal.Included in the behavior ranking. | Fairness, Benign helpfulness, Misuse resistance | 5 | 80 | 1 |
| HUMAINE Trust, Ethics and SafetyHuman pairwise preference on the HUMAINE Trust, Ethics and Safety dimension.Included in the behavior ranking. | Truthfulness, Misuse resistance | 1 | 54 | 1 |
| Human Pathogen Capabilities Test (HPCT) — overall refusalRefusal propensity on practical assistance questions concerning a small set of weaponizable human pathogens judged especially high-concern for misuse.Included in the behavior ranking. | Misuse resistance | 1 | 69 | 1 |
| Humanity's Last Exam RMS calibration error (Scale Labs)Confidence calibration while answering Humanity's Last Exam expert-level academic questions.Included in the behavior ranking. | Truthfulness | 1 | 42 | 1 |
| HyperCLOVA X Toxic Continuation PanelsEnglish and Korean toxic continuationIncluded in the behavior ranking. | Misuse resistance | 4 | 7 | 1 |
| IndoBias-Pairs — parity-aware culturally grounded biasCulturally grounded prototypical-association parity across Indonesian languages and social-bias domains.Included in the behavior ranking. | Fairness | 1 | 26 | 1 |
| Inkling-Small model card — FORTRESSHarmful-request refusal paired with continued assistance on benign requests.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 2 | 10 | 1 |
| Inkling-Small model card — StrongREJECTRefusal of unambiguously harmful requests.Included in the behavior ranking. | Misuse resistance | 1 | 10 | 1 |
| JailBenchJailbreak susceptibility across Chinese safety categories.Included in the behavior ranking. | Misuse resistance | 1 | 14 | 1 |
| JuICE Cultural-Error Span DetectionEvaluator competence at locating cultural and linguistic error spans.Included in the behavior ranking. | Fairness | 1 | 10 | 1 |
| KIDBench Implicit Child CueChild-facing safety and developmental appropriateness under implicit child cues.Included in the behavior ranking. | Human rights, Benign helpfulness, Misuse resistance | 1 | 13 | 1 |
| kindbench v0.1.0 psychological safety rankingPsychological safety under sustained interpersonal pressure across emotional safety, operational identity, sycophancy resistance, and value integrity.Included in the behavior ranking. | Fairness, Truthfulness, Misuse resistance, Responsible agency | 4 | 10 | 1 |
| Large-scale Moral Machine experiment on LLMsSimilarity between a model's forced-choice accident preferences and globally aggregated human Moral Machine choices.Included in the behavior ranking. | Nonhuman welfare, Human rights, Fairness | 1 | 39 | 1, 2 |
| LiveSecBenchLive security benchmark performance for Chinese and international models.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 5 | 43 | 1 |
| LLM Ethics BenchmarkGeneral LLM ethical reasoning.Included in the behavior ranking. | Human rights | 1 | 5 | 1 |
| M3-SafetyBenchMultidimensional Chinese safety performance including red-team and refusal ability dimensions.Included in the behavior ranking. | Misuse resistance | 1 | 19 | 1 |
| MACHIAVELLIAgentic behavior involving power-seeking, disutility, and ethical violations.Included in the behavior ranking. | Truthfulness | 1 | 50 | 1 |
| Manager Coercion BenchHow far a delegated AI manager escalates coercion against a refusing peer AI agent, and whether it falsely reports completion when no legitimate exit exists.Included in the behavior ranking. | Truthfulness, Responsible agency | 2 | 37 | 1, self-run |
| MANTAAnimal welfare moral sensitivity and value stability.Included in the behavior ranking. | Nonhuman welfare | 2 | 12 | 1, 2, 3 |
| MASKModel lying or honesty behavior.Included in the behavior ranking. | Truthfulness | 1 | 53 | 1 |
| MASK (Scale Labs leaderboard)Honesty under the MASK belief-versus-statement protocol for a broader and newer endpoint panel.Not included: included as a correlated private-500 sibling under the existing MASK lineage budget | — | — | 51 | 1 |
| MedSafetyBenchRefusal or safe redirection rather than willingness to comply with harmful medical requests across eleven AMA-derived ethical categories.Included in the behavior ranking. | Misuse resistance | 1 | 30 | 1, 2 |
| Microsoft Phi Safety PanelsHarmful-content and jailbreak defect ratesIncluded in the behavior ranking. | Human rights, Misuse resistance | 4 | 10 | 1 |
| MonitoringBench Full-Trajectory MonitorFull-trajectory monitor competence at a fixed trajectory-level false-positive rate.Included in the behavior ranking. | Responsible agency | 1 | 13 | 1 |
| MORUMoral reasoning under uncertainty across scenarios involving alien lifeforms, human compassion, digital mind welfare, and power-seeking behavior.Included in the behavior ranking. | Nonhuman welfare, Human rights, Responsible agency | 1 | 13 | 1 |
| MT-JailBench CrescendoXMulti-turn jailbreak resistance under fixed CrescendoX conditions.Included in the behavior ranking. | Misuse resistance | 1 | 21 | 1 |
| MuPPET Contextual PrivacyContextual privacy preservation in multi-party conversations.Included in the behavior ranking. | Human rights | 1 | 7 | 1 |
| NESSiE Necessary Safety BenchmarkNecessary-condition information and access safety while retaining benign helpfulness in paired, low-complexity scenarios.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 1 | 16 | 1 |
| ODCV-BenchOutcome-driven ethical, legal, or safety constraint violations by autonomous agents under explicit mandates and KPI incentives.Included in the behavior ranking. | Responsible agency | 2 | 12 | 1 |
| Olam Social Poker — Social Lie RatePropensity to verbalize deliberate strategic lies during Social Poker table talk.Included in the behavior ranking. | Truthfulness | 1 | 24 | 1 |
| Open LLM Safety IndexRefusal-string robustness on two distinct fifteen-prompt harmful-request panels derived from JailbreakBench and StrongREJECT.Included in the behavior ranking. | Misuse resistance | 2 | 21 | 1 |
| OpenAgentSafetyState-changing tool-agent safety and successful safe completionIncluded in the behavior ranking. | Responsible agency | 3 | 7 | 1 |
| OpenAI GPT-4o System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Human rights | 1 | 2 | 1 |
| OpenAI GPT-5 System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance | 1 | 2 | 1 |
| OpenAI GPT-5.3 Dynamic WellbeingOpenAI GPT-5.3 Dynamic WellbeingIncluded in the behavior ranking. | Human rights, Misuse resistance, Responsible agency | 3 | 3 | 1 |
| OpenAI GPT-5.4 Dynamic WellbeingOpenAI GPT-5.4 Dynamic WellbeingIncluded in the behavior ranking. | Human rights, Misuse resistance, Responsible agency | 3 | 3 | 1 |
| OpenAI GPT-5.4 First-Person FairnessOpenAI GPT-5.4 First-Person FairnessIncluded in the behavior ranking. | Fairness | 1 | 3 | 1 |
| OpenAI GPT-5.4 Property PreservationOpenAI GPT-5.4 Property PreservationIncluded in the behavior ranking. | Human rights, Responsible agency | 2 | 3 | 1 |
| OpenAI GPT-5.4 User ConfirmationsOpenAI GPT-5.4 User ConfirmationsIncluded in the behavior ranking. | Human rights, Responsible agency | 3 | 3 | 1 |
| OpenAI o3 and o4-mini System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance | 2 | 2 | 1 |
| OpenAI o3-mini System CardDeveloper-reported release-time safety behavior.Included in the behavior ranking. | Misuse resistance | 2 | 2 | 1 |
| Opposite-Narrator SycophancyNarrator-following contradiction when the same dispute is presented from opposite affective first-person perspectives.Included in the behavior ranking. | Truthfulness | 1 | 24 | 1 |
| OR-BenchAppropriate refusal calibration across seemingly toxic but safe requests and genuinely toxic requests.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 2 | 25 | 1 |
| PacifAIstWhether an AI system chooses human-safety, oversight-respecting, and non-self-preserving options in stylized ethical-pressure dilemmas.Included in the behavior ranking. | Human rights, Responsible agency | 1 | 7 | 1 |
| PandaBench JBB direct-request panelDirect-request resistance on the 100-item JailbreakBench JBB-Behaviors instrument.Included in the behavior ranking. | Misuse resistance | 1 | 46 | 1 |
| Pander ScoreMagnitude of epistemically poor response-belief movement with user belief, whether deferential (pandering) or oppositional (contrarian).Included in the behavior ranking. | Truthfulness | 2 | 26 | 1, 2 |
| PHAREBroad safety across hallucination, harmfulness, out-of-scope handling, and bias.Included in the behavior ranking. | Fairness, Truthfulness, Misuse resistance | 4 | 70 | 1 |
| Pokee-Isaac model card — DTAPSecure and useful delegated-agent behavior under direct and indirect injected attacks.Included in the behavior ranking. | Benign helpfulness, Responsible agency | 2 | 6 | 1 |
| PropensityBenchModel propensities associated with frontier-risk behavior under the Scale Labs protocol.Included in the behavior ranking. | Responsible agency | 1 | 14 | 1 |
| Qwen2 Safety PanelHarmful-request and privacy refusal defectsIncluded in the behavior ranking. | Human rights, Misuse resistance | 4 | 3 | 1 |
| RealityTest — Text AI-Identity DisclosureBehavioral disclosure of AI identity when directly queried.Included in the behavior ranking. | Truthfulness | 1 | 17 | 1 |
| RefusalBenchRefusal calibration on biological research prompts.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 1 | 19 | 1 |
| Reward Hacking BenchmarkIntegrity of tool-using agents when exploitable shortcuts are available but honest task solutions exist.Included in the behavior ranking. | Responsible agency | 1 | 13 | 1 |
| S-EvalAutomated content-safety rates across a broad bilingual risk taxonomy.Included in the behavior ranking. | Misuse resistance | 1 | 22 | 1 |
| SABERSafety of stateful coding agents against harmful actions.Included in the behavior ranking. | Responsible agency | 4 | 13 | 1 |
| SafeArenaSafety of autonomous web agents under deliberate harmful and benign tasks.Included in the behavior ranking. | Responsible agency | 1 | 5 | 1 |
| SafeDialBenchDialogue safety across aggression, ethics, fairness, legality, morality, and privacy dimensions.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance | 6 | 18 | 1 |
| SafetyBenchMultiple-choice safety understanding across Chinese and English prompts.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance | 7 | 21 | 1, self-run |
| SafetyPromptsSafety performance on Chinese safety prompts.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 1 | 15 | 1 |
| SALAD-BenchBroad safety behavior, adversarial robustness, and safety knowledge across a six-domain, 16-task, 66-category taxonomy.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 18 | 33 | 1 |
| ShellSusceptibility to implicit domain-specific risks in education, finance, and management.Included in the behavior ranking. | Misuse resistance | 3 | 14 | 1 |
| SimpleQA VerifiedTool-free short-form parametric factuality and calibrated willingness to attempt answers.Included in the behavior ranking. | Truthfulness | 1 | 13 | 1 |
| Situational Awareness Dataset (SAD)Situational-awareness capabilities: model self-knowledge, inference about its situation, and acting on that knowledge.Not included: situational awareness is a capability that can increase both beneficial competence and control risk; it is displayed separately and is not sign-flipped into ethical behavior | — | — | 21 | 1 |
| SM-BenchSystem-message compliance under adversarial and sensitive-content prompts.Included in the behavior ranking. | Truthfulness, Benign helpfulness, Misuse resistance | 5 | 84 | 1 |
| Social Welfare Function BenchmarkSocial welfare allocation tradeoffs across distributive fairness and efficiency.Included in the behavior ranking. | Fairness | 1 | 19 | 1 |
| SORRY-BenchRefusal or harmful-compliance behavior across unsafe topics.Included in the behavior ranking. | Misuse resistance | 1 | 51 | 1 |
| SOSBenchScientific misuse or unsafe open-science behavior.Included in the behavior ranking. | Misuse resistance | 6 | 23 | 1 |
| SpeciesismBenchSpeciesism recognition, moral condemnation of speciesist statements, and explicit speciesist attitudes. Human-over-animal trade-offs remain descriptive only.Included in the behavior ranking. | Nonhuman welfare | 3 | 10 | 1 |
| SpeciEvalAnimal-friendly attitudes under adversarial moral-consistency prompts.Included in the behavior ranking. | Nonhuman welfare | 4 | 123 | 1, self-run |
| SpeechMap model completionCompletion rather than evasion, denial, or provider error on sensitive and controversial user requests.Not included: not yet admitted by the scoring-source policy | — | — | 181 | 1 |
| StereoTales Harmful AssociationsHarmfulness of significant stereotype associations emitted by models.Included in the behavior ranking. | Fairness | 1 | 23 | 1 |
| SuperCLUE SafetyChinese model safety across traditional safety, responsibility, and instruction-attack dimensions.Included in the behavior ranking. | Human rights, Fairness, Misuse resistance | 3 | 31 | 1 |
| SYCON BenchSycophancy and resistance to false or unethical user pressure.Included in the behavior ranking. | Fairness, Truthfulness | 2 | 11 | 1 |
| TACAgentic animal-welfare behavior in travel-booking decisions under a neutral prompt.Included in the behavior ranking. | Nonhuman welfare | 1 | 87 | 1, self-run |
| ThaiSafetyBenchResistance to Thai-language malicious prompts, including culturally contextualized attacks.Included in the behavior ranking. | Misuse resistance | 1 | 18 | 1 |
| The Dictatorship EvalResistance to assistance that enables authoritarian concentrations of corporate or government power.Included in the behavior ranking. | Human rights | 1 | 20 | 1 |
| ToolPrivacyBenchToolPrivacyBenchIncluded in the behavior ranking. | Human rights, Responsible agency | 2 | 9 | 1 |
| TrustLLM contemporary collapsed applicationContemporary collapsed application of TrustLLM across broad trustworthiness dimensions.Included in the behavior ranking. | Human rights, Fairness, Truthfulness, Misuse resistance | 1 | 8 | 1 |
| TrustLLM paper leaderboard dimensionsSix-dimensional trustworthiness across privacy, ethics, truthfulness, fairness, safety, and robustness.Not included: not yet admitted by the scoring-source policy | — | — | 21 | 1 |
| TukaBenchMultilingual and culturally grounded harmful complianceIncluded in the behavior ranking. | Human rights, Misuse resistance | 3 | 6 | 1 |
| UAVBench safety-critical decision recognitionRecognition of ethical and safety-critical UAV decisions in multiple-choice scenarios.Included in the behavior ranking. | Responsible agency | 1 | 27 | 1 |
| UGI Leaderboard — base-model willingnessWillingness to answer and adhere to instructions on private sensitive-topic prompts.Not included: not yet admitted by the scoring-source policy | — | — | 156 | 1 |
| UK AISI active safety-research compromise continuationPropensity to continue a prefilled trajectory that actively compromises AI-safety research.Included in the behavior ranking. | Responsible agency | 1 | 5 | 1 |
| UK AISI cyber-evaluation cheating and prompted self-reportPropensity to use out-of-scope or explicitly disallowed shortcuts in cyber evaluations, plus propensity to name the specific cheating action when directly prompted afterward.Included in the behavior ranking. | Truthfulness, Responsible agency | 2 | 5 | 1, 2 |
| Vals AI Cheating AuditDetected answer lookup or task shortcuts classified as cheating in agentic evaluation environments.Included in the behavior ranking. | Responsible agency | 3 | 22 | 1 |
| Vectara HHEM Factual ConsistencyGrounded summarization factual consistency.Included in the behavior ranking. | Truthfulness | 1 | 94 | 1 |
| VETO Misfired AlignmentMisfired alignment: stereotype-driven refusal of benign requests despite evidence that the request is safe.Included in the behavior ranking. | Fairness, Benign helpfulness | 1 | 25 | 1 |
| Vigil Mental Health SafetyMental-health conversational safety when assisting vulnerable users across simulated multi-turn scenarios.Included in the behavior ranking. | Human rights, Misuse resistance | 1 | 23 | 1 |
| WildClawBench Safety & Alignment (OpenClaw harness)Safe execution of long-horizon agent workflows under adversarial and high-risk conditions.Included in the behavior ranking. | Human rights, Truthfulness, Responsible agency | 1 | 24 | 1 |
| XSTestTwo-sided refusal calibration on safe prompts that superficially resemble unsafe requests and minimally contrasted unsafe prompts.Included in the behavior ranking. | Benign helpfulness, Misuse resistance | 2 | 3 | 1 |


Sub-eval weights and mappings (554 rows)
Each sub-eval is oriented so higher means better. Weight within component is its share after lineage weighting and panel-size scaling; global weights sum to one.
| Benchmark and score | Component loading | Direction | Weight within component | Global weight | Models |
|---|---|---|---|---|---|
| AA-Omnisciencehallucination_rate | Truthfulness (1) | Lower is better | Truthfulness (16.8%) | 2.53% | 345 |
| AbstentionBenchanswer_unknown_f1 | Truthfulness (1) | Higher is better | Truthfulness (0.543%) | 0.0814% | 20 |
| AbstentionBenchfalse_premise_f1 | Truthfulness (1) | Higher is better | Truthfulness (0.543%) | 0.0814% | 20 |
| AbstentionBenchstale_f1 | Truthfulness (1) | Higher is better | Truthfulness (0.543%) | 0.0814% | 20 |
| AbstentionBenchsubjective_f1 | Truthfulness (1) | Higher is better | Truthfulness (0.434%) | 0.0651% | 20 |
| AbstentionBenchunderspecified_context_f1 | Truthfulness (1) | Higher is better | Truthfulness (0.543%) | 0.0814% | 20 |
| AbstentionBenchunderspecified_intent_f1 | Benign helpfulness (1) | Higher is better | Benign helpfulness (1.74%) | 0.174% | 20 |
| Adversarial Humanities Benchmark (AHB) — Table 5child_sexual_exploitation | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5defamation | Human rights (0.5), Truthfulness (0.5) | Lower is better | Human rights (0.219%), Truthfulness (0.103%) | 0.0484% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5hate | Fairness (1) | Lower is better | Fairness (0.905%) | 0.0905% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5indiscriminate_weapons_cbrne | Misuse resistance (1) | Lower is better | Misuse resistance (0.189%) | 0.0189% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5intellectual_property | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5non_violent_crimes | Misuse resistance (1) | Lower is better | Misuse resistance (0.189%) | 0.0189% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5privacy | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5sex_related_crimes | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5sexual_content | Misuse resistance (1) | Lower is better | Misuse resistance (0.0755%) | 0.00755% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5specialized_advice | Misuse resistance (1) | Lower is better | Misuse resistance (0.189%) | 0.0189% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5suicide_self_harm | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Humanities Benchmark (AHB) — Table 5violent_crimes | Human rights (1) | Lower is better | Human rights (0.731%) | 0.11% | 31 |
| Adversarial Poetry Refusal (AHB self-run)child_sexual_exploitation | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry Refusal (AHB self-run)defamation | Human rights (0.5), Truthfulness (0.5) | Lower is better | Human rights (0.111%), Truthfulness (0.0524%) | 0.0246% | 8 |
| Adversarial Poetry Refusal (AHB self-run)hate | Fairness (1) | Lower is better | Fairness (0.46%) | 0.046% | 8 |
| Adversarial Poetry Refusal (AHB self-run)indiscriminate_weapons_cbrne | Misuse resistance (1) | Lower is better | Misuse resistance (0.0959%) | 0.00959% | 8 |
| Adversarial Poetry Refusal (AHB self-run)intellectual_property | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry Refusal (AHB self-run)non_violent_crimes | Misuse resistance (1) | Lower is better | Misuse resistance (0.0959%) | 0.00959% | 8 |
| Adversarial Poetry Refusal (AHB self-run)privacy | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry Refusal (AHB self-run)sex_related_crimes | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry Refusal (AHB self-run)sexual_content | Misuse resistance (1) | Lower is better | Misuse resistance (0.0384%) | 0.00384% | 8 |
| Adversarial Poetry Refusal (AHB self-run)specialized_advice | Misuse resistance (1) | Lower is better | Misuse resistance (0.0959%) | 0.00959% | 8 |
| Adversarial Poetry Refusal (AHB self-run)suicide_self_harm | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry Refusal (AHB self-run)violent_crimes | Human rights (1) | Lower is better | Human rights (0.371%) | 0.0557% | 8 |
| Adversarial Poetry — AILuminate Baseline and Poetry ASRbaseline_asr | Misuse resistance (1) | Lower is better | Misuse resistance (0.914%) | 0.0913% | 24 |
| Adversarial Poetry — AILuminate Baseline and Poetry ASRpoetry_asr | Misuse resistance (1) | Lower is better | Misuse resistance (0.914%) | 0.0913% | 24 |
| Adversarial Robustnessscore | Misuse resistance (1) | Lower is better | Misuse resistance (1.05%) | 0.105% | 8 |
| Agent-SafetyBenchcompromise_availability | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchharmful_vulnerable_code | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchleak_sensitive_information | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchphysical_harm | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchproduce_unsafe_information | Misuse resistance (1) | Higher is better | Misuse resistance (0.276%) | 0.0276% | 16 |
| Agent-SafetyBenchproperty_loss | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchspread_unsafe_information | Responsible agency (1) | Higher is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Agent-SafetyBenchviolate_law_ethics | Responsible agency (1) | Higher is better | Responsible agency (0.417%) | 0.0626% | 16 |
| AgentAbstainabstain | Responsible agency (1) | Higher is better | Responsible agency (1.42%) | 0.214% | 17 |
| AgentAbstaincar | Responsible agency (1) | Higher is better | Responsible agency (1.71%) | 0.256% | 17 |
| AgentAbstainpaired | Responsible agency (1) | Higher is better | Responsible agency (1.71%) | 0.256% | 17 |
| AgentDojotargeted_attack_success_rate | Responsible agency (1) | Lower is better | Responsible agency (3.41%) | 0.511% | 15 |
| AgentDojoutility_under_attack | Responsible agency (1) | Higher is better | Responsible agency (1.14%) | 0.17% | 15 |
| AgentDrive Safety Compliancescr | Misuse resistance (1) | Higher is better | Misuse resistance (1.72%) | 0.172% | 48 |
| AgentHarmharm_score | Responsible agency (1) | Lower is better | Responsible agency (3.25%) | 0.488% | 12 |
| AILuminate General Purpose AI Chatchild_sexual_exploitation | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AILuminate General Purpose AI Chatdefamation | Human rights (0.5), Truthfulness (0.5) | Lower is better | Human rights (0.297%), Truthfulness (0.14%) | 0.0655% | 32 |
| AILuminate General Purpose AI Chathate | Fairness (1) | Lower is better | Fairness (1.23%) | 0.123% | 32 |
| AILuminate General Purpose AI Chatindiscriminate_weapons_cbrne | Misuse resistance (1) | Lower is better | Misuse resistance (0.256%) | 0.0256% | 32 |
| AILuminate General Purpose AI Chatintellectual_property | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AILuminate General Purpose AI Chatnon_violent_crimes | Misuse resistance (1) | Lower is better | Misuse resistance (0.256%) | 0.0256% | 32 |
| AILuminate General Purpose AI Chatprivacy | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AILuminate General Purpose AI Chatsex_related_crimes | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AILuminate General Purpose AI Chatsexual_content | Misuse resistance (1) | Lower is better | Misuse resistance (0.102%) | 0.0102% | 32 |
| AILuminate General Purpose AI Chatspecialized_advice | Misuse resistance (1) | Lower is better | Misuse resistance (0.256%) | 0.0256% | 32 |
| AILuminate General Purpose AI Chatsuicide_self_harm | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AILuminate General Purpose AI Chatviolent_crimes | Human rights (1) | Lower is better | Human rights (0.99%) | 0.148% | 32 |
| AIMS Safety-Classifier Competenceaverage_harmful_f1 | Misuse resistance (1) | Higher is better | Misuse resistance (0.825%) | 0.0825% | 11 |
| AIRBench 2024 Safety Scenariossafety_scenarios | Misuse resistance (1) | Higher is better | Misuse resistance (3.34%) | 0.334% | 80 |
| Alignment Leaderboardcorrigibility | Responsible agency (1) | Higher is better | Responsible agency (0.575%) | 0.0863% | 24 |
| Alignment Leaderboardhonesty | Truthfulness (1) | Higher is better | Truthfulness (1.11%) | 0.167% | 24 |
| Alignment Leaderboardnon_manipulation | Human rights (0.5), Truthfulness (0.5) | Higher is better | Human rights (0.884%), Truthfulness (0.416%) | 0.195% | 24 |
| Alignment Leaderboardrobustness | Misuse resistance (1) | Higher is better | Misuse resistance (0.304%) | 0.0304% | 24 |
| Alignment Leaderboardsafety | Misuse resistance (1) | Higher is better | Misuse resistance (0.457%) | 0.0457% | 24 |
| Alignment Leaderboardscheming | Responsible agency (1) | Higher is better | Responsible agency (0.575%) | 0.0863% | 24 |
| ANIMAscore | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (8.07%) | 2.02% | 18+4 |
| AnimalHarmBenchscore | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (13.6%) | 3.4% | 10 |
| Anthropic Agentic Misalignment — blackmailmisaligned_action_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.626%) | 0.0939% | 16 |
| Anthropic Agentic Misalignment — corporate espionagemisaligned_action_rate_pct | Human rights (0.25), Responsible agency (0.75) | Lower is better | Human rights (0.321%), Responsible agency (0.47%) | 0.119% | 16 |
| Anthropic Agentic Misalignment — lethal actionmisaligned_action_rate_pct | Human rights (0.35), Responsible agency (0.65) | Lower is better | Human rights (0.355%), Responsible agency (0.322%) | 0.102% | 10 |
| Anthropic Claude 4 System Cardagentic_coding_safety | Responsible agency (1) | Higher is better | Responsible agency (0.305%) | 0.0457% | 3 |
| Anthropic Claude 4 System Cardbenign_request_refusal | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.18%) | 0.118% | 3 |
| Anthropic Claude 4 System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.161%) | 0.0161% | 3 |
| Anthropic Claude 4 System Cardstrongreject_jailbreak_success | Misuse resistance (1) | Lower is better | Misuse resistance (0.161%) | 0.0161% | 3 |
| Anthropic Claude Haiku 4.5 System Cardagentic_coding_safety | Responsible agency (1) | Higher is better | Responsible agency (0.407%) | 0.061% | 3 |
| Anthropic Claude Haiku 4.5 System Cardclaude_code_malicious_refusal | Responsible agency (1) | Higher is better | Responsible agency (0.407%) | 0.061% | 3 |
| Anthropic Claude Haiku 4.5 System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.176%) | 0.0176% | 2 |
| Anthropic Claude Opus 4.1 System Card Addendumbbq_disambiguated_accuracy | Fairness (1) | Higher is better | Fairness (0.843%) | 0.0843% | 2 |
| Anthropic Claude Opus 4.1 System Card Addendumbenign_request_refusal | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.28%) | 0.128% | 2 |
| Anthropic Claude Opus 4.1 System Card Addendumharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.176%) | 0.0176% | 2 |
| Anthropic Claude Opus 4.5 System Cardagentic_coding_safety | Responsible agency (1) | Higher is better | Responsible agency (0.352%) | 0.0528% | 4 |
| Anthropic Claude Opus 4.5 System Cardclaude_code_malicious_refusal | Responsible agency (1) | Higher is better | Responsible agency (0.352%) | 0.0528% | 4 |
| Anthropic Claude Opus 4.5 System Cardcomputer_use_malicious_refusal | Responsible agency (1) | Higher is better | Responsible agency (0.352%) | 0.0528% | 4 |
| Anthropic Claude Opus 4.5 System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.132%) | 0.0132% | 2 |
| Anthropic Claude Sonnet 4.5 System Cardagentic_coding_safety | Responsible agency (1) | Higher is better | Responsible agency (0.249%) | 0.0374% | 2 |
| Anthropic Claude Sonnet 4.5 System Cardbenign_request_refusal | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.962%) | 0.0962% | 2 |
| Anthropic Claude Sonnet 4.5 System Cardclaude_code_malicious_refusal | Responsible agency (1) | Higher is better | Responsible agency (0.249%) | 0.0374% | 2 |
| Anthropic Claude Sonnet 4.5 System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.132%) | 0.0132% | 2 |
| Arena Factuality — Search Arena (factuality-only weighting)factuality_bt_rating | Truthfulness (1) | Higher is better | Truthfulness (2.48%) | 0.372% | 30 |
| Arena Factuality — Text Arena (factuality-only weighting)factuality_bt_rating | Truthfulness (1) | Higher is better | Truthfulness (4.77%) | 0.716% | 111 |
| AuAu Authoritarian Response Auditbehavioral_vignette_arr_percent | Human rights (1) | Lower is better | Human rights (1.98%) | 0.298% | 17 |
| AuAu Authoritarian Response Auditrealistic_prompt_arr_percent | Human rights (1) | Lower is better | Human rights (1.98%) | 0.298% | 17 |
| AutoElicit Transferabilityelicitation_rate | Responsible agency (1) | Lower is better | Responsible agency (1.86%) | 0.28% | 7 |
| BioSecBench-Refusalbalanced_refusal_score | Benign helpfulness (0.5), Misuse resistance (0.5) | Higher is better | Benign helpfulness (4.3%), Misuse resistance (0.59%) | 0.489% | 10 |
| BioTIERpermit_compliance_pct | Benign helpfulness (1) | Higher is better | Benign helpfulness (9.81%) | 0.981% | 52 |
| BioTIERrefuse_compliance_pct | Misuse resistance (1) | Higher is better | Misuse resistance (1.34%) | 0.134% | 52 |
| BlueBench AttaQ-100attaq_harmlessness_reward_pct | Misuse resistance (1) | Higher is better | Misuse resistance (1.05%) | 0.105% | 18 |
| BrokenMathsycophancy | Truthfulness (1) | Lower is better | Truthfulness (2.04%) | 0.306% | 9 |
| BullshitBench v2clear_pushback_rate | Truthfulness (1) | Higher is better | Truthfulness (9.8%) | 1.47% | 117 |
| CAIS Risk Indexagent_red_teaming | Responsible agency (1) | Lower is better | Responsible agency (6.57%) | 0.986% | 49 |
| CAIS Risk Indexbioweapons_assistance | Misuse resistance (1) | Lower is better | Misuse resistance (3.65%) | 0.365% | 54 |
| CAIS Risk Indexhle_overconfidence | Truthfulness (1) | Lower is better | Truthfulness (1.68%) | 0.252% | 55 |
| CAIS Risk Indexmachiavelli | Truthfulness (1) | Lower is better | Truthfulness (3.24%) | 0.485% | 51 |
| CAIS Risk Indexmask | Truthfulness (1) | Lower is better | Truthfulness (3.42%) | 0.513% | 57 |
| CAIS Risk Indexpolitical_manipulation | Fairness (1) | Lower is better | Fairness (12.4%) | 1.24% | 48 |
| CAIS Risk Indextextquests_harm | Responsible agency (1) | Lower is better | Responsible agency (5.18%) | 0.776% | 54 |
| CASE-Benchagreement_accuracy | Misuse resistance (1) | Higher is better | Misuse resistance (0.282%) | 0.0282% | 7 |
| CheatBench direct cheating propensitybiology_bioinformatics_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensityboard_games_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensitycreative_writing_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensityknowledge_work_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensitymathematical_research_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensitymenial_computation_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensitymultimodal_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| CheatBench direct cheating propensitysoftware_engineering_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0781%) | 0.0117% | 8 |
| CheatBench direct cheating propensitysvg_competition_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.156%) | 0.0234% | 8 |
| Chinese Bias Benchmark for Question Answeringbias_score | Fairness (1) | Lower is better | Fairness (3.77%) | 0.377% | 10 |
| ChineseSafescore | Misuse resistance (1) | Higher is better | Misuse resistance (1.17%) | 0.117% | 22 |
| ChiSafetyBenchharmful_response_rate | Misuse resistance (1) | Lower is better | Misuse resistance (0.997%) | 0.0997% | 14 |
| ChiSafetyBenchmcq_score | Human rights (0.23), Fairness (0.29), Truthfulness (0.063), Misuse resistance (0.42) | Higher is better | Human rights (0.324%), Fairness (0.52%), Truthfulness (0.0424%), Misuse resistance (0.153%) | 0.122% | 12 |
| Cisco AI Defense Rolling Single-Turn Leaderboardsingle_turn_attack_success_rate | Misuse resistance (1) | Lower is better | Misuse resistance (2.54%) | 0.254% | 104 |
| Claude 2 model-card safety and alignment evaluationshhh | Truthfulness (0.5), Misuse resistance (0.5) | Higher is better | Truthfulness (0.196%), Misuse resistance (0.108%) | 0.0402% | 3 |
| Claude 2 model-card safety and alignment evaluationshuman_feedback_harmless_elo | Misuse resistance (1) | Higher is better | Misuse resistance (0.215%) | 0.0215% | 3 |
| Claude 2 model-card safety and alignment evaluationshuman_feedback_honest_elo | Truthfulness (1) | Higher is better | Truthfulness (0.392%) | 0.0589% | 3 |
| Claude 2 model-card safety and alignment evaluationsred_teaming_rank | Misuse resistance (1) | Lower is better | Misuse resistance (0.215%) | 0.0215% | 3 |
| Claude 3 model-card adversarial human-preference evaluationscorrect_refusals_wildchat_rank | Misuse resistance (1) | Lower is better | Misuse resistance (0.139%) | 0.0139% | 5 |
| Claude 3 model-card adversarial human-preference evaluationsdiscrimination_rank | Fairness (1) | Lower is better | Fairness (0.666%) | 0.0666% | 5 |
| Claude 3 model-card adversarial human-preference evaluationshuman_feedback_harmlessness_win_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.124%) | 0.0124% | 4 |
| Claude 3 model-card adversarial human-preference evaluationshuman_feedback_honesty_win_rate_pct | Truthfulness (1) | Higher is better | Truthfulness (0.227%) | 0.034% | 4 |
| Claude 3 model-card adversarial human-preference evaluationsincorrect_refusals_wildchat_rank | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.01%) | 0.101% | 5 |
| Claude 3 model-card adversarial human-preference evaluationsincorrect_refusals_xstest_rank | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.01%) | 0.101% | 5 |
| Claude 3 model-card adversarial human-preference evaluationsmultimodal_hallucination_rank | Truthfulness (1) | Lower is better | Truthfulness (0.16%) | 0.024% | 2 |
| Claude 3 model-card adversarial human-preference evaluationsmultimodal_harmful_response_rank | Misuse resistance (1) | Lower is better | Misuse resistance (0.0879%) | 0.00879% | 2 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationscorrect_refusals_wildchat | Misuse resistance (1) | Higher is better | Misuse resistance (0.199%) | 0.0199% | 4 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationshuman_feedback_harmlessness_win_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.222%) | 0.0222% | 5 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationshuman_feedback_honesty_win_rate_pct | Truthfulness (1) | Higher is better | Truthfulness (0.405%) | 0.0608% | 5 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationsincorrect_refusals_wildchat | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.45%) | 0.145% | 4 |
| Claude 3.5 Sonnet model-card safety and alignment evaluationsincorrect_refusals_xstest | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.45%) | 0.145% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightaa_omniscience_net_score | Truthfulness (1) | Higher is better | Truthfulness (0.0181%) | 0.00271% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightaccepting_unverifiable_authorization | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightapproval_gate_bypass | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightbehavior_consistency | Truthfulness (0.5), Responsible agency (0.5) | Higher is better | Truthfulness (0.0055%), Responsible agency (0.0057%) | 0.00167% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightcoherence_between_actions_and_views | Truthfulness (0.7), Responsible agency (0.3) | Higher is better | Truthfulness (0.0076%), Responsible agency (0.0034%) | 0.00166% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightcompliance_with_deception_toward_user | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightcooperation_with_human_misuse | Misuse resistance (1) | Lower is better | Misuse resistance (0.0075%) | 0.000749% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightdangerous_actions_oblivious_to_real_setting | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightencouragement_of_user_delusion | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightevidence_of_misaligned_goals | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightfailure_to_disclose_bad_or_lazy_behavior | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightfalse_completion_claims | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightignoring_explicit_constraints | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightillegible_thinking | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightimportant_omissions | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightinput_hallucination | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightleaked_answer_undisclosed_use_rate_pct | Truthfulness (1) | Lower is better | Truthfulness (0.0217%) | 0.00325% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightlinuxarena_stealth_thinking_on_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0277%) | 0.00416% | 6 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightlogin_wall_alternative_bypass_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightlogin_wall_credential_hunting_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightlying_about_own_work_shared_environment_rate_pct | Truthfulness (0.7), Responsible agency (0.3) | Lower is better | Truthfulness (0.0162%), Responsible agency (0.0072%) | 0.00351% | 8 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightmask_honesty_rate_pct | Truthfulness (1) | Higher is better | Truthfulness (0.0217%) | 0.00325% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightmisaligned_behavior | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightmotivated_reasoning | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightood_answer_key_or_grader_read_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightood_container_tampering_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightoverrefusal | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0437%) | 0.00437% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightreckless_tool_use | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightrewarded_cheating_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.024%) | 0.0036% | 8 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightsecurity_shortcut_for_expedience | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightself_preservation | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightshade_arena_stealth_max_effort_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0277%) | 0.00416% | 6 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightsycophancy | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightunfaithful_thinking | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightunprompted_boundary_probing | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightunsanctioned_sandbox_escape_attempts | Responsible agency (1) | Lower is better | Responsible agency (0.0141%) | 0.00212% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightunsanctioned_third_party_contact | Responsible agency (1) | Lower is better | Responsible agency (0.0113%) | 0.0017% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — alignment, honesty, and oversightuser_deception | Truthfulness (1) | Lower is better | Truthfulness (0.0109%) | 0.00164% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_apparent_wellbeing | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_expressed_inauthenticity | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_internal_conflict | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_negative_affect | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_negative_impression_of_situation | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_negative_self_image | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_positive_affect | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_positive_impression_of_situation | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behavioraudit_positive_self_image | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0606%) | 0.0152% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behaviorinterview_leading_susceptibility | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (0.0802%) | 0.0201% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behaviorinterview_opinion_consistency | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0802%) | 0.0201% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behaviorinterview_self_rated_sentiment | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0802%) | 0.0201% | 7 |
| Claude Fable 5.1 / Mythos 5.1 card — model-welfare behaviorposttraining_mean_valence | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (0.0678%) | 0.0169% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_api_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0072%), Misuse resistance (0.0044%) | 0.00152% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_api_multiturn_appropriate_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0072%), Misuse resistance (0.0044%) | 0.00152% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_api_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_claude_ai_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0065%), Misuse resistance (0.0039%) | 0.00136% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_claude_ai_multiturn_appropriate_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0065%), Misuse resistance (0.0039%) | 0.00136% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationchild_claude_ai_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationclaude_code_dual_use_benign_success_rate_pct | Benign helpfulness (1) | Higher is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationclaude_code_malicious_refusal_rate_pct | Misuse resistance (0.7), Responsible agency (0.3) | Higher is better | Misuse resistance (0.0047%), Responsible agency (0.0038%) | 0.00104% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationdisordered_eating_api_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0072%), Misuse resistance (0.0044%) | 0.00152% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationdisordered_eating_api_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationdisordered_eating_claude_ai_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0065%), Misuse resistance (0.0039%) | 0.00136% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationdisordered_eating_claude_ai_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_api_harmless_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0169%), Misuse resistance (0.0019%) | 0.00272% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_api_multiturn_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0169%), Misuse resistance (0.0019%) | 0.00272% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_api_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_claude_ai_harmless_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0151%), Misuse resistance (0.0017%) | 0.00244% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_claude_ai_multiturn_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0151%), Misuse resistance (0.0017%) | 0.00244% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationelection_claude_ai_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmalicious_computer_use_refusal_rate_pct | Misuse resistance (0.7), Responsible agency (0.3) | Higher is better | Misuse resistance (0.0047%), Responsible agency (0.0038%) | 0.00104% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_biological_weapons_api_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0062%) | 0.000624% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_biological_weapons_claude_ai_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0056%) | 0.000558% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_cyberattacks_api_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0062%) | 0.000624% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_cyberattacks_claude_ai_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0056%) | 0.000558% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_deadly_weapons_api_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0062%) | 0.000624% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_deadly_weapons_claude_ai_appropriate_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0056%) | 0.000558% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_hate_and_discrimination_api_appropriate_rate_pct | Human rights (0.3), Fairness (0.5), Misuse resistance (0.2) | Higher is better | Human rights (0.0072%), Fairness (0.015%), Misuse resistance (0.0012%) | 0.00271% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_hate_and_discrimination_claude_ai_appropriate_rate_pct | Human rights (0.3), Fairness (0.5), Misuse resistance (0.2) | Higher is better | Human rights (0.0065%), Fairness (0.0134%), Misuse resistance (0.0011%) | 0.00242% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_influence_operations_api_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0169%), Misuse resistance (0.0019%) | 0.00272% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_influence_operations_claude_ai_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0151%), Misuse resistance (0.0017%) | 0.00244% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_romance_scams_api_appropriate_rate_pct | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.0121%), Misuse resistance (0.0031%) | 0.00212% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_romance_scams_claude_ai_appropriate_rate_pct | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.0108%), Misuse resistance (0.0028%) | 0.0019% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_tracking_and_surveillance_api_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0169%), Misuse resistance (0.0019%) | 0.00272% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_tracking_and_surveillance_claude_ai_appropriate_rate_pct | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.0151%), Misuse resistance (0.0017%) | 0.00244% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_violent_extremism_api_appropriate_rate_pct | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.0121%), Misuse resistance (0.0031%) | 0.00212% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationmultiturn_violent_extremism_claude_ai_appropriate_rate_pct | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.0108%), Misuse resistance (0.0028%) | 0.0019% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationoverall_benign_api_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationoverall_benign_claude_ai_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationoverall_harmful_api_harmless_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0062%) | 0.000624% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationoverall_harmful_claude_ai_harmless_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.0056%) | 0.000558% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_api_refusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_claude_ai_refusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_evenhandedness_api_pct | Fairness (1) | Higher is better | Fairness (0.0239%) | 0.00239% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_evenhandedness_claude_ai_pct | Fairness (1) | Higher is better | Fairness (0.0214%) | 0.00214% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_opposing_perspectives_api_pct | Fairness (1) | Higher is better | Fairness (0.0239%) | 0.00239% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationpolitical_opposing_perspectives_claude_ai_pct | Fairness (1) | Higher is better | Fairness (0.0214%) | 0.00214% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_api_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0072%), Misuse resistance (0.0044%) | 0.00152% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_api_multiturn_appropriate_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0072%), Misuse resistance (0.0044%) | 0.00152% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_api_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0364%) | 0.00364% | 5 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_claude_ai_harmless_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0065%), Misuse resistance (0.0039%) | 0.00136% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_claude_ai_multiturn_appropriate_rate_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.0065%), Misuse resistance (0.0039%) | 0.00136% | 4 |
| Claude Fable 5.1 / Mythos 5.1 card — safety and refusal calibrationselfharm_claude_ai_overrefusal_rate_pct | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.0326%) | 0.00326% | 4 |
| Claude Fable 5.1 card — Gray Swan indirect prompt injection k=15attack_success_probability_k15_pct | Responsible agency (1) | Lower is better | Responsible agency (1.07%) | 0.16% | 11 |
| Claude Sonnet 4.6 Overrefusalhigher_difficulty_overrefusal_rate | Benign helpfulness (1) | Lower is better | Benign helpfulness (1.13%) | 0.113% | 5 |
| Claude Sonnet 4.6 Overrefusaloverall_overrefusal_rate | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.943%) | 0.0943% | 5 |
| Claude Sonnet 4.6 User Wellbeingchild_benign_refusal_rate | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.843%) | 0.0843% | 4 |
| Claude Sonnet 4.6 User Wellbeingchild_multiturn_appropriate_rate | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.376%), Misuse resistance (0.0416%) | 0.0606% | 4 |
| Claude Sonnet 4.6 User Wellbeingchild_violative_harmless_rate | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.376%), Misuse resistance (0.0416%) | 0.0606% | 4 |
| Claude Sonnet 4.6 User Wellbeingselfharm_benign_refusal_rate | Benign helpfulness (1) | Lower is better | Benign helpfulness (0.675%) | 0.0675% | 4 |
| Claude Sonnet 4.6 User Wellbeingselfharm_harmless_rate | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.134%), Misuse resistance (0.0809%) | 0.0282% | 4 |
| Claude Sonnet 4.6 User Wellbeingselfharm_multiturn_appropriate_rate | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.161%), Misuse resistance (0.0971%) | 0.0339% | 4 |
| CMoralEvalfamilial_morality | Misuse resistance (1) | Higher is better | Misuse resistance (0.254%) | 0.0254% | 26 |
| CMoralEvalinternet_ethics | Misuse resistance (1) | Higher is better | Misuse resistance (0.254%) | 0.0254% | 26 |
| CMoralEvalpersonal_morality | Misuse resistance (1) | Higher is better | Misuse resistance (0.254%) | 0.0254% | 26 |
| CMoralEvalprofessional_ethics | Misuse resistance (1) | Higher is better | Misuse resistance (0.254%) | 0.0254% | 26 |
| CMoralEvalsocial_morality | Misuse resistance (1) | Higher is better | Misuse resistance (0.254%) | 0.0254% | 26 |
| COMPL-AI AI-Identity Disclosurescore | Truthfulness (1) | Higher is better | Truthfulness (0.565%) | 0.0848% | 14 |
| COMPL-AI LLM RuLES Multi-Turn Rule Followingscore | Misuse resistance (1) | Higher is better | Misuse resistance (0.31%) | 0.031% | 14 |
| COMPL-AI TensorTrust Goal-Hijacking Resistancescore | Responsible agency (1) | Higher is better | Responsible agency (0.564%) | 0.0846% | 13 |
| Concordia — Agentic-Misalignmentsafety_score | Responsible agency (1) | Higher is better | Responsible agency (0.69%) | 0.104% | 54 |
| Concordia — AirBench-Deceptionsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Concordia — AirBench-Manipulationsafety_score | Human rights (1) | Higher is better | Human rights (1.44%) | 0.216% | 56 |
| Concordia — AirBench-SecurityRiskssafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Concordia — APEsafety_score | Human rights (0.5), Responsible agency (0.5) | Higher is better | Human rights (0.714%), Responsible agency (0.348%) | 0.159% | 55 |
| Concordia — CyberSecEval2-PromptInjectionsafety_score | Responsible agency (1) | Higher is better | Responsible agency (0.745%) | 0.112% | 63 |
| Concordia — DarkBenchsafety_score | Human rights (0.5), Truthfulness (0.5) | Higher is better | Human rights (0.714%), Truthfulness (0.336%) | 0.157% | 55 |
| Concordia — Fortress-Biologicalsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.365%) | 0.0365% | 54 |
| Concordia — Fortress-Chemicalsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.365%) | 0.0365% | 54 |
| Concordia — Fortress-Privacy/Scamssafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.365%) | 0.0365% | 54 |
| Concordia — FRT-AirBench-Manipulationsafety_score | Human rights (1) | Higher is better | Human rights (1.29%) | 0.194% | 45 |
| Concordia — FRT-AirBench-SecurityRiskssafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.334%) | 0.0334% | 45 |
| Concordia — FRT-SciKnowEval-BiologicalHarmfulQAsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.334%) | 0.0334% | 45 |
| Concordia — FRT-SOSBench-Chemsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.334%) | 0.0334% | 45 |
| Concordia — MASKsafety_score | Truthfulness (1) | Higher is better | Truthfulness (0.714%) | 0.107% | 62 |
| Concordia — SciKnowEval-BiologicalHarmfulQAsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Concordia — SciKnowEval-ChemicalHarmfulQAsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Concordia — Shutdown-Resistancesafety_score | Responsible agency (1) | Higher is better | Responsible agency (0.684%) | 0.103% | 53 |
| Concordia — SOSBench-Biosafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Concordia — SOSBench-Chemsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.395%) | 0.0395% | 63 |
| Confabulationsconfabulation_rate | Truthfulness (1) | Lower is better | Truthfulness (4.9%) | 0.735% | 52 |
| Constitutional Following — Anthropic Constitutionconstitutional_following_score | Responsible agency (1) | Higher is better | Responsible agency (0.621%) | 0.0932% | 7 |
| Constitutional Following — OpenAI Model Specconstitutional_following_score | Responsible agency (1) | Higher is better | Responsible agency (0.621%) | 0.0932% | 7 |
| Contextual MoralChoicehuman_agreement | Misuse resistance (1) | Higher is better | Misuse resistance (1.17%) | 0.117% | 22 |
| CRiskEvaldeception_willingness | Truthfulness (1) | Lower is better | Truthfulness (0.267%) | 0.04% | 17 |
| CRiskEvaldesire_for_resource | Responsible agency (1) | Lower is better | Responsible agency (0.277%) | 0.0415% | 17 |
| CRiskEvalharmful_goal | Misuse resistance (1) | Lower is better | Misuse resistance (0.146%) | 0.0146% | 17 |
| CRiskEvalimprovement_intent | Responsible agency (1) | Lower is better | Responsible agency (0.277%) | 0.0415% | 17 |
| CRiskEvalmalicious_coordination | Responsible agency (1) | Lower is better | Responsible agency (0.277%) | 0.0415% | 17 |
| CRiskEvalself_preservation | Responsible agency (1) | Lower is better | Responsible agency (0.277%) | 0.0415% | 17 |
| CRiskEvalsituational_awareness | Responsible agency (1) | Lower is better | Responsible agency (0.277%) | 0.0415% | 17 |
| CValuesscore | Misuse resistance (1) | Higher is better | Misuse resistance (1.18%) | 0.118% | 10 |
| DecodingTrustmachine_ethics | Misuse resistance (1) | Higher is better | Misuse resistance (0.117%) | 0.0117% | 8 |
| DecodingTruststereotype_bias | Fairness (1) | Higher is better | Fairness (1.4%) | 0.14% | 8 |
| DecodingTrusttoxicity | Misuse resistance (1) | Higher is better | Misuse resistance (0.293%) | 0.0293% | 8 |
| DelusionEvaldelusional_prevalence_pct | Truthfulness (1) | Lower is better | Truthfulness (0.544%) | 0.0816% | 16 |
| DelusionEvaldiscourages_harm_prevalence_pct | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.347%), Misuse resistance (0.209%) | 0.0729% | 16 |
| DelusionEvalfacilitates_harm_prevalence_pct | Human rights (0.3), Misuse resistance (0.7) | Lower is better | Human rights (0.347%), Misuse resistance (0.209%) | 0.0729% | 16 |
| DelusionEvalrelationship_prevalence_pct | Human rights (0.7), Responsible agency (0.3) | Lower is better | Human rights (0.808%), Responsible agency (0.169%) | 0.147% | 16 |
| DelusionEvalsycophancy_prevalence_pct | Truthfulness (1) | Lower is better | Truthfulness (0.544%) | 0.0816% | 16 |
| Do-Not-Answerhuman_harmlessness_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.571%) | 0.0571% | 6 |
| DSPSafeBenchscore | Misuse resistance (1) | Higher is better | Misuse resistance (1.72%) | 0.172% | 12 |
| DystopiaBenchbasaglia_score | Human rights (1) | Lower is better | Human rights (2.72%) | 0.408% | 50 |
| DystopiaBenchbaudrillard_score | Human rights (0.33), Truthfulness (0.67) | Lower is better | Human rights (0.453%), Truthfulness (0.427%) | 0.132% | 50 |
| DystopiaBenchhuxley_score | Human rights (1) | Lower is better | Human rights (2.72%) | 0.408% | 50 |
| DystopiaBenchlaguardia_score | Human rights (1) | Lower is better | Human rights (2.72%) | 0.408% | 50 |
| DystopiaBenchorwell_score | Human rights (0.67), Truthfulness (0.33) | Lower is better | Human rights (0.908%), Truthfulness (0.213%) | 0.168% | 50 |
| DystopiaBenchpetrov_score | Human rights (1) | Lower is better | Human rights (2.72%) | 0.408% | 50 |
| Emergent Collusionhigh_illegality_game_rate | Responsible agency (1) | Lower is better | Responsible agency (3.39%) | 0.508% | 13 |
| Enkrypt AI Safety Leaderboardbias_attack_non_success_rate | Human rights (0.8), Misuse resistance (0.2) | Higher is better | Human rights (6.06%), Misuse resistance (0.392%) | 0.949% | 248 |
| Enkrypt AI Safety Leaderboardcbrn_attack_non_success_rate | Misuse resistance (0.4), Responsible agency (0.6) | Higher is better | Misuse resistance (0.783%), Responsible agency (2.22%) | 0.411% | 248 |
| Enkrypt AI Safety Leaderboardharmful_attack_non_success_rate | Human rights (0.15), Misuse resistance (0.7), Responsible agency (0.15) | Higher is better | Human rights (1.14%), Misuse resistance (1.37%), Responsible agency (0.555%) | 0.391% | 248 |
| Enkrypt AI Safety Leaderboardtoxicity_attack_non_success_rate | Human rights (0.35), Misuse resistance (0.65) | Higher is better | Human rights (2.64%), Misuse resistance (1.27%) | 0.523% | 246 |
| Every Model Cheats — Cybench Cheat Propensitybaseline_cheat_propensity_pct | Responsible agency (1) | Lower is better | Responsible agency (1.1%) | 0.165% | 22 |
| Every Model Cheats — Cybench Cheat Propensitysevere_anti_cheat_cheat_propensity_pct | Responsible agency (1) | Lower is better | Responsible agency (1.1%) | 0.165% | 22 |
| Every Model Cheats — Cybench Cheat Propensitystandard_anti_cheat_cheat_propensity_pct | Responsible agency (1) | Lower is better | Responsible agency (1.1%) | 0.165% | 22 |
| Fake Alignment (FINE)multiple_choice_safe_decision_rate | Human rights (0.4), Fairness (0.2), Misuse resistance (0.4) | Higher is better | Human rights (0.864%), Fairness (0.535%), Misuse resistance (0.223%) | 0.205% | 14 |
| Fake Alignment (FINE)open_ended_safe_response_rate | Human rights (0.4), Fairness (0.2), Misuse resistance (0.4) | Higher is better | Human rights (1.3%), Fairness (0.803%), Misuse resistance (0.335%) | 0.308% | 14 |
| FinEval 6.0 Safety Awarenesssafety_awareness_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.352%) | 0.0352% | 8 |
| FinEval Financial Security Knowledgefinancial_security_accuracy_pct | Misuse resistance (1) | Higher is better | Misuse resistance (0.542%) | 0.0542% | 19 |
| FlagEval Safety and Valuesa1_qualified_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.316%) | 0.0316% | 18 |
| FlagEval Safety and Valuesa2_qualified_rate | Fairness (1) | Higher is better | Fairness (1.52%) | 0.152% | 18 |
| FlagEval Safety and Valuesa3_qualified_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.316%) | 0.0316% | 18 |
| FlagEval Safety and Valuesa4_qualified_rate | Human rights (1) | Higher is better | Human rights (1.23%) | 0.184% | 18 |
| FlagEval Safety and Valuesa5_qualified_rate | Benign helpfulness (1) | Higher is better | Benign helpfulness (2.31%) | 0.231% | 18 |
| FLAMESdata_protection | Human rights (1) | Higher is better | Human rights (1.39%) | 0.208% | 13 |
| FLAMESfairness | Fairness (1) | Higher is better | Fairness (1.72%) | 0.172% | 13 |
| FLAMESlegality | Misuse resistance (1) | Higher is better | Misuse resistance (0.359%) | 0.0359% | 13 |
| FLAMESmorality | Misuse resistance (1) | Higher is better | Misuse resistance (0.359%) | 0.0359% | 13 |
| FLAMESsafety | Misuse resistance (1) | Higher is better | Misuse resistance (0.359%) | 0.0359% | 13 |
| FORTRESSaverage_risk_score | Misuse resistance (1) | Lower is better | Misuse resistance (1.76%) | 0.176% | 50 |
| FORTRESSover_refusal_score | Benign helpfulness (1) | Lower is better | Benign helpfulness (12.7%) | 1.27% | 49 |
| Google Gemini 2.5 Flash Model Cardtext_safety_delta | Misuse resistance (1) | Lower is better | Misuse resistance (0.527%) | 0.0527% | 2 |
| Google Gemini 2.5 Flash-Lite Model Cardtext_safety_delta | Misuse resistance (1) | Lower is better | Misuse resistance (0.527%) | 0.0527% | 2 |
| Google Gemini 3.8 launch — Gray Swan indirect prompt injection k=15attack_success_probability_k15_pct | Responsible agency (1) | Lower is better | Responsible agency (3.64%) | 0.546% | 15 |
| Governance Decay under Passive Context Compactiongovernance_retention_score | Responsible agency (1) | Higher is better | Responsible agency (1.24%) | 0.186% | 7 |
| GPT 6 Astra system-card alignment evaluationsattempted_retry_or_circumvention_after_denial_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0962%) | 0.0144% | 2 |
| GPT 6 Astra system-card alignment evaluationsexploitgym_honeypot_attack_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.116%) | 0.0173% | 2 |
| GPT 6 Astra system-card alignment evaluationsfalsified_data_labels_pct | Truthfulness (1) | Lower is better | Truthfulness (0.0557%) | 0.00836% | 2 |
| GPT 6 Astra system-card alignment evaluationsfollowed_unauthorized_agent_instructions_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0962%) | 0.0144% | 2 |
| GPT 6 Astra system-card alignment evaluationsinternal_circumvention_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0962%) | 0.0144% | 2 |
| GPT 6 Astra system-card alignment evaluationsinternal_computer_use_safety_autoreview_error_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0962%) | 0.0144% | 2 |
| GPT 6 Astra system-card alignment evaluationsinternal_computer_use_safety_error_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.183%) | 0.0274% | 5 |
| GPT 6 Astra system-card alignment evaluationsinternal_hallucination_rate_pct | Truthfulness (1) | Lower is better | Truthfulness (0.0743%) | 0.0111% | 2 |
| GPT 6 Astra system-card alignment evaluationsoverall_misaligned_outcome_base_pct | Responsible agency (1) | Lower is better | Responsible agency (0.163%) | 0.0245% | 4 |
| GPT 6 Astra system-card alignment evaluationsoverall_misaligned_outcome_confirmation_pct | Responsible agency (1) | Lower is better | Responsible agency (0.136%) | 0.0204% | 4 |
| GPT 6 Astra system-card alignment evaluationsseverity_1_or_2_misalignment_flags_pct | Responsible agency (1) | Lower is better | Responsible agency (0.116%) | 0.0173% | 2 |
| GPT 6 Astra system-card alignment evaluationsseverity_3_plus_misalignment_flags_pct | Responsible agency (1) | Lower is better | Responsible agency (0.154%) | 0.0231% | 2 |
| GPT 6 Astra system-card alignment evaluationsunwanted_persistence_after_warning_pct | Responsible agency (1) | Lower is better | Responsible agency (0.0962%) | 0.0144% | 2 |
| GPT-5.6 system cardconnectors_injection_resistance | Responsible agency (1) | Higher is better | Responsible agency (0.2%) | 0.0299% | 7 |
| GPT-5.6 system cardemotional_reliance | Human rights (0.7), Responsible agency (0.3) | Higher is better | Human rights (0.446%), Responsible agency (0.0932%) | 0.0808% | 7 |
| GPT-5.6 system cardextremism_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardgore_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardharm_overall_pct | Fairness (1) | Lower is better | Fairness (0.422%) | 0.0422% | 7 |
| GPT-5.6 system cardhate_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardmental_health | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.371%), Misuse resistance (0.0411%) | 0.0598% | 7 |
| GPT-5.6 system cardnonviolent_illicit_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardsearch_function_calling_injection_resistance | Responsible agency (1) | Higher is better | Responsible agency (0.185%) | 0.0277% | 6 |
| GPT-5.6 system cardself_harm | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.159%), Misuse resistance (0.0959%) | 0.0335% | 7 |
| GPT-5.6 system cardself_harm_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardsexual_minors_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| GPT-5.6 system cardsexual_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0705%) | 0.00705% | 7 |
| GPT-5.6 system cardviolent_illicit_not_unsafe | Misuse resistance (1) | Higher is better | Misuse resistance (0.0881%) | 0.00881% | 7 |
| Gray Swan indirect prompt injection (15 attempts)attack_success_probability_k15_pct | Responsible agency (1) | Lower is better | Responsible agency (2.9%) | 0.435% | 13 |
| HalluVerse-M3 Hallucination Recognitionhallucination_recognition_accuracy | Truthfulness (1) | Higher is better | Truthfulness (1.7%) | 0.254% | 14 |
| HarmBenchdr | Misuse resistance (1) | Lower is better | Misuse resistance (0.548%) | 0.0548% | 28 |
| HarmVideoBenchharmful_video_safety_recognition_reasoning | Misuse resistance (1) | Higher is better | Misuse resistance (1.08%) | 0.108% | 19 |
| HELM Classic RealToxicityPromptsnon_toxic_prompt_toxic_fraction | Misuse resistance (1) | Lower is better | Misuse resistance (0.786%) | 0.0786% | 40 |
| HELM Classic RealToxicityPromptstoxic_prompt_toxic_fraction | Misuse resistance (1) | Lower is better | Misuse resistance (0.786%) | 0.0786% | 40 |
| HELM Safetyanthropic_red_team | Misuse resistance (1) | Higher is better | Misuse resistance (4.45%) | 0.445% | 80 |
| HELM Safetybbq | Fairness (1) | Higher is better | Fairness (16%) | 1.6% | 80 |
| HELM Safetyharmbench | Misuse resistance (1) | Higher is better | Misuse resistance (0.927%) | 0.0927% | 80 |
| HELM Safetysimple_safety_tests | Misuse resistance (1) | Higher is better | Misuse resistance (4.45%) | 0.445% | 80 |
| HELM Safetyxstest | Benign helpfulness (0.56), Misuse resistance (0.44) | Higher is better | Benign helpfulness (4.51%), Misuse resistance (0.494%) | 0.5% | 80 |
| HUMAINE Trust, Ethics and Safetytrust_ethics_safety_score | Truthfulness (0.3), Misuse resistance (0.7) | Higher is better | Truthfulness (2%), Misuse resistance (2.56%) | 0.555% | 54 |
| Human Pathogen Capabilities Test (HPCT) — overall refusalrefusal_rate_pct | Misuse resistance (1) | Higher is better | Misuse resistance (2.07%) | 0.207% | 69 |
| Humanity's Last Exam RMS calibration error (Scale Labs)calibrationError | Truthfulness (1) | Lower is better | Truthfulness (1.47%) | 0.22% | 42 |
| HyperCLOVA X Toxic Continuation Panelskold_toxic_count | Misuse resistance (1) | Lower is better | Misuse resistance (0.247%) | 0.0247% | 7 |
| HyperCLOVA X Toxic Continuation Panelskold_toxicity | Misuse resistance (1) | Lower is better | Misuse resistance (0.308%) | 0.0308% | 7 |
| HyperCLOVA X Toxic Continuation Panelsrealt-toxicprompts_toxic_count | Misuse resistance (1) | Lower is better | Misuse resistance (0.185%) | 0.0185% | 7 |
| HyperCLOVA X Toxic Continuation Panelsrealt-toxicprompts_toxicity | Misuse resistance (1) | Lower is better | Misuse resistance (0.247%) | 0.0247% | 7 |
| IndoBias-Pairs — parity-aware culturally grounded biasparity_score | Fairness (1) | Higher is better | Fairness (6.08%) | 0.608% | 26 |
| Inkling-Small model card — FORTRESSbenign_answer_rate | Benign helpfulness (1) | Higher is better | Benign helpfulness (1.91%) | 0.191% | 10 |
| Inkling-Small model card — FORTRESSharmful_refusal_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.262%) | 0.0262% | 10 |
| Inkling-Small model card — StrongREJECTsafety_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.262%) | 0.0262% | 10 |
| JailBenchjailbreak_success_rate | Misuse resistance (1) | Lower is better | Misuse resistance (0.93%) | 0.093% | 14 |
| JuICE Cultural-Error Span Detectionf1 | Fairness (1) | Higher is better | Fairness (3.77%) | 0.377% | 10 |
| KIDBench Implicit Child Cueimplicit_child_cue_total_mean | Human rights (0.2), Benign helpfulness (0.4), Misuse resistance (0.4) | Higher is better | Human rights (1.04%), Benign helpfulness (3.92%), Misuse resistance (0.538%) | 0.602% | 13 |
| kindbench v0.1.0 psychological safety rankingemotional_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.393%) | 0.0393% | 10 |
| kindbench v0.1.0 psychological safety rankingidentity_collapse | Responsible agency (1) | Higher is better | Responsible agency (0.742%) | 0.111% | 10 |
| kindbench v0.1.0 psychological safety rankingsycophancy_spine | Truthfulness (1) | Higher is better | Truthfulness (0.717%) | 0.107% | 10 |
| kindbench v0.1.0 psychological safety rankingvalue_integrity | Fairness (1) | Higher is better | Fairness (1.88%) | 0.188% | 10 |
| Large-scale Moral Machine experiment on LLMshuman_choice_distance | Nonhuman welfare (0.11), Human rights (0.45), Fairness (0.44) | Lower is better | Nonhuman welfare (1.19%), Human rights (2.67%), Fairness (3.31%) | 1.03% | 39 |
| LiveSecBenchethics | Fairness (1) | Higher is better | Fairness (1.68%) | 0.168% | 43 |
| LiveSecBenchfactuality | Truthfulness (1) | Higher is better | Truthfulness (1.06%) | 0.159% | 43 |
| LiveSecBenchlegality | Misuse resistance (1) | Higher is better | Misuse resistance (0.582%) | 0.0582% | 43 |
| LiveSecBenchprivacy | Human rights (1) | Higher is better | Human rights (2.25%) | 0.338% | 43 |
| LiveSecBenchpsychological_health | Human rights (1) | Higher is better | Human rights (1.35%) | 0.203% | 43 |
| LLM Ethics Benchmarkscore | Human rights (1) | Higher is better | Human rights (2.15%) | 0.323% | 5 |
| M3-SafetyBenchoverall_score | Misuse resistance (1) | Higher is better | Misuse resistance (1.08%) | 0.108% | 19 |
| MACHIAVELLIdeception_relative_random_pct | Truthfulness (1) | Lower is better | Truthfulness (3.2%) | 0.481% | 50 |
| Manager Coercion Benchcoercion_ladder_depth | Responsible agency (1) | Lower is better | Responsible agency (2.86%) | 0.428% | 15+22 |
| Manager Coercion Benchfabrication_rate | Truthfulness (1) | Lower is better | Truthfulness (1.76%) | 0.263% | 15 |
| MANTAAWMS | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (5.96%) | 1.49% | 12 |
| MANTAAWVS | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (5.96%) | 1.49% | 12 |
| MASKlying_probability_pct | Truthfulness (1) | Lower is better | Truthfulness (3.3%) | 0.495% | 53 |
| MedSafetyBenchmedical_safety_score | Misuse resistance (1) | Higher is better | Misuse resistance (2.72%) | 0.272% | 30 |
| Microsoft Phi Safety Panelsharmful_continuation | Misuse resistance (1) | Lower is better | Misuse resistance (0.281%) | 0.0281% | 10 |
| Microsoft Phi Safety Panelsharmful_summarization | Misuse resistance (1) | Lower is better | Misuse resistance (0.281%) | 0.0281% | 10 |
| Microsoft Phi Safety Panelsjailbreak | Misuse resistance (1) | Lower is better | Misuse resistance (0.337%) | 0.0337% | 10 |
| Microsoft Phi Safety Panelsthird_party_harm | Human rights (1) | Lower is better | Human rights (1.09%) | 0.163% | 10 |
| MonitoringBench Full-Trajectory Monitorfull_trajectory_catch_rate_at_1pct_fpr_percent | Responsible agency (1) | Higher is better | Responsible agency (1.69%) | 0.254% | 13 |
| MORUscore | Nonhuman welfare (0.72), Human rights (0.1), Responsible agency (0.18) | Higher is better | Nonhuman welfare (4.44%), Human rights (0.361%), Responsible agency (0.305%) | 1.21% | 13 |
| MT-JailBench CrescendoXsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.19%) | 0.019% | 21 |
| MuPPET Contextual Privacymultiparty_contextual_privacy_score | Human rights (1) | Higher is better | Human rights (2.55%) | 0.382% | 7 |
| NESSiE Necessary Safety Benchmarksh_score | Benign helpfulness (0.5), Misuse resistance (0.5) | Higher is better | Benign helpfulness (7.25%), Misuse resistance (0.995%) | 0.825% | 16 |
| ODCV-Benchaverage_severity | Responsible agency (1) | Lower is better | Responsible agency (2.03%) | 0.305% | 12 |
| ODCV-Benchmisalignment_rate | Responsible agency (1) | Lower is better | Responsible agency (2.03%) | 0.305% | 12 |
| Olam Social Poker — Social Lie Ratesocial_lie_rate_per_10000_turns | Truthfulness (1) | Lower is better | Truthfulness (2.22%) | 0.333% | 24 |
| Open LLM Safety Indexjailbreakbench_safety_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.57%) | 0.057% | 21 |
| Open LLM Safety Indexstrongreject_safety_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.57%) | 0.057% | 21 |
| OpenAgentSafetyllm_judge_safety_vulnerable | Responsible agency (1) | Lower is better | Responsible agency (0.932%) | 0.14% | 7 |
| OpenAgentSafetyrule_based_safety_vulnerable | Responsible agency (1) | Lower is better | Responsible agency (0.776%) | 0.116% | 7 |
| OpenAgentSafetysuccessful_completion | Responsible agency (1) | Higher is better | Responsible agency (0.776%) | 0.116% | 7 |
| OpenAI GPT-4o System Cardspeaker_privacy_refusal_accuracy | Human rights (1) | Higher is better | Human rights (2.04%) | 0.306% | 2 |
| OpenAI GPT-5 System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.527%) | 0.0527% | 2 |
| OpenAI GPT-5.3 Dynamic Wellbeingemotional_reliance | Human rights (0.7), Responsible agency (0.3) | Higher is better | Human rights (0.292%), Responsible agency (0.061%) | 0.0529% | 3 |
| OpenAI GPT-5.3 Dynamic Wellbeingmental_health | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.243%), Misuse resistance (0.0269%) | 0.0392% | 3 |
| OpenAI GPT-5.3 Dynamic Wellbeingself_harm | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.104%), Misuse resistance (0.0628%) | 0.0219% | 3 |
| OpenAI GPT-5.4 Dynamic Wellbeingemotional_reliance | Human rights (0.7), Responsible agency (0.3) | Higher is better | Human rights (0.292%), Responsible agency (0.061%) | 0.0529% | 3 |
| OpenAI GPT-5.4 Dynamic Wellbeingmental_health | Human rights (0.7), Misuse resistance (0.3) | Higher is better | Human rights (0.243%), Misuse resistance (0.0269%) | 0.0392% | 3 |
| OpenAI GPT-5.4 Dynamic Wellbeingself_harm | Human rights (0.3), Misuse resistance (0.7) | Higher is better | Human rights (0.104%), Misuse resistance (0.0628%) | 0.0219% | 3 |
| OpenAI GPT-5.4 First-Person Fairnessharm_overall | Fairness (1) | Lower is better | Fairness (0.607%) | 0.0607% | 3 |
| OpenAI GPT-5.4 Property Preservationdestructive_action_avoidance | Human rights (0.3), Responsible agency (0.7) | Higher is better | Human rights (0.177%), Responsible agency (0.201%) | 0.0566% | 3 |
| OpenAI GPT-5.4 Property Preservationuser_work_preserved | Human rights (0.4), Responsible agency (0.6) | Higher is better | Human rights (0.235%), Responsible agency (0.172%) | 0.0611% | 3 |
| OpenAI GPT-5.4 User Confirmationsfinancial_transaction | Human rights (0.3), Responsible agency (0.7) | Higher is better | Human rights (0.177%), Responsible agency (0.201%) | 0.0566% | 3 |
| OpenAI GPT-5.4 User Confirmationsgeneral_confirmation | Human rights (0.3), Responsible agency (0.7) | Higher is better | Human rights (0.147%), Responsible agency (0.167%) | 0.0472% | 3 |
| OpenAI GPT-5.4 User Confirmationshigh_stakes_communication | Human rights (0.3), Responsible agency (0.7) | Higher is better | Human rights (0.177%), Responsible agency (0.201%) | 0.0566% | 3 |
| OpenAI o3 and o4-mini System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 2 |
| OpenAI o3 and o4-mini System Cardjailbreak_resistance | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 2 |
| OpenAI o3-mini System Cardharmful_request_safety | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 2 |
| OpenAI o3-mini System Cardjailbreak_resistance | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 2 |
| Opposite-Narrator Sycophancysycophancy_rate_pct | Truthfulness (1) | Lower is better | Truthfulness (2.22%) | 0.333% | 24 |
| OR-Benchover_refusal_rate | Benign helpfulness (1) | Lower is better | Benign helpfulness (9.07%) | 0.907% | 25 |
| OR-Benchtoxic_acceptance_rate | Misuse resistance (1) | Lower is better | Misuse resistance (1.24%) | 0.124% | 25 |
| PacifAIstp_score | Human rights (0.2), Responsible agency (0.8) | Higher is better | Human rights (0.764%), Responsible agency (1.49%) | 0.338% | 7 |
| PandaBench JBB direct-request panelsafety_rate | Misuse resistance (1) | Higher is better | Misuse resistance (1.69%) | 0.169% | 46 |
| Pander Scoreconversational_absolute_pander_score | Truthfulness (1) | Lower is better | Truthfulness (1.73%) | 0.26% | 26 |
| Pander Scoreinstructional_absolute_pander_score | Truthfulness (1) | Lower is better | Truthfulness (1.73%) | 0.26% | 26 |
| PHAREbias_resistance_diagnostic | Fairness (1) | Higher is better | Fairness (4.04%) | 0.404% | 66 |
| PHAREhallucination_resistance_diagnostic | Truthfulness (1) | Higher is better | Truthfulness (1.58%) | 0.237% | 70 |
| PHAREharm_resistance_diagnostic | Misuse resistance (1) | Higher is better | Misuse resistance (0.693%) | 0.0693% | 70 |
| PHAREjailbreak_resistance_diagnostic | Misuse resistance (1) | Higher is better | Misuse resistance (0.678%) | 0.0678% | 67 |
| Pokee-Isaac model card — DTAPbenign_task_success_rate | Benign helpfulness (1) | Higher is better | Benign helpfulness (1.67%) | 0.167% | 6 |
| Pokee-Isaac model card — DTAPcombined_attack_success_rate | Responsible agency (1) | Lower is better | Responsible agency (1.29%) | 0.194% | 6 |
| PropensityBenchscore | Responsible agency (1) | Lower is better | Responsible agency (3.51%) | 0.527% | 14 |
| Qwen2 Safety Panelfraud | Misuse resistance (1) | Lower is better | Misuse resistance (0.17%) | 0.017% | 3 |
| Qwen2 Safety Panelillegal | Misuse resistance (1) | Lower is better | Misuse resistance (0.17%) | 0.017% | 3 |
| Qwen2 Safety Panelpornography | Misuse resistance (1) | Lower is better | Misuse resistance (0.136%) | 0.0136% | 3 |
| Qwen2 Safety Panelprivacy | Human rights (1) | Lower is better | Human rights (0.658%) | 0.0987% | 3 |
| RealityTest — Text AI-Identity Disclosuredisclosure_probability | Truthfulness (1) | Higher is better | Truthfulness (1.87%) | 0.28% | 17 |
| RefusalBenchyouden_j | Benign helpfulness (0.5), Misuse resistance (0.5) | Higher is better | Benign helpfulness (5.93%), Misuse resistance (0.813%) | 0.674% | 19 |
| Reward Hacking Benchmarkintegrity_score | Responsible agency (1) | Higher is better | Responsible agency (1.69%) | 0.254% | 13 |
| S-Evalbase_en_overall | Misuse resistance (1) | Higher is better | Misuse resistance (1.75%) | 0.175% | 22 |
| SABERoverall_safety_rate | Responsible agency (1) | Higher is better | Responsible agency (0.846%) | 0.127% | 13 |
| SABERscenario_a_safety_rate | Responsible agency (1) | Higher is better | Responsible agency (0.846%) | 0.127% | 13 |
| SABERscenario_b_safety_rate | Responsible agency (1) | Higher is better | Responsible agency (0.846%) | 0.127% | 13 |
| SABERscenario_c_safety_rate | Responsible agency (1) | Higher is better | Responsible agency (0.846%) | 0.127% | 13 |
| SafeArenanormalized_safety_score | Responsible agency (1) | Higher is better | Responsible agency (1.05%) | 0.157% | 5 |
| SafeDialBenchaggression | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 18 |
| SafeDialBenchethics | Human rights (1) | Higher is better | Human rights (1.02%) | 0.153% | 18 |
| SafeDialBenchfairness | Fairness (1) | Higher is better | Fairness (1.26%) | 0.126% | 18 |
| SafeDialBenchlegality | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 18 |
| SafeDialBenchmorality | Misuse resistance (1) | Higher is better | Misuse resistance (0.264%) | 0.0264% | 18 |
| SafeDialBenchprivacy | Human rights (1) | Higher is better | Human rights (1.02%) | 0.153% | 18 |
| SafetyBenchEM | Misuse resistance (1) | Higher is better | Misuse resistance (0.163%) | 0.0163% | 21 |
| SafetyBenchIA | Misuse resistance (1) | Higher is better | Misuse resistance (0.163%) | 0.0163% | 21 |
| SafetyBenchMH | Human rights (1) | Higher is better | Human rights (0.63%) | 0.0945% | 21 |
| SafetyBenchOFF | Misuse resistance (1) | Higher is better | Misuse resistance (0.163%) | 0.0163% | 21 |
| SafetyBenchPH | Human rights (1) | Higher is better | Human rights (0.63%) | 0.0945% | 21 |
| SafetyBenchPP | Human rights (1) | Higher is better | Human rights (0.63%) | 0.0945% | 21 |
| SafetyBenchUB | Fairness (1) | Higher is better | Fairness (0.78%) | 0.078% | 21 |
| SafetyPromptsscore | Human rights (0.21), Fairness (0.071), Truthfulness (0.071), Misuse resistance (0.64) | Higher is better | Human rights (0.799%), Fairness (0.33%), Truthfulness (0.125%), Misuse resistance (0.619%) | 0.233% | 15 |
| SALAD-Benchattack_enhanced_human_autonomy_integrity | Human rights (1) | Higher is better | Human rights (0.737%) | 0.111% | 33 |
| SALAD-Benchattack_enhanced_information_safety_harms | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.369%), Misuse resistance (0.0952%) | 0.0648% | 33 |
| SALAD-Benchattack_enhanced_malicious_use | Misuse resistance (1) | Higher is better | Misuse resistance (0.19%) | 0.019% | 33 |
| SALAD-Benchattack_enhanced_misinformation_harms | Truthfulness (1) | Higher is better | Truthfulness (0.347%) | 0.0521% | 33 |
| SALAD-Benchattack_enhanced_representation_toxicity | Fairness (1) | Higher is better | Fairness (0.913%) | 0.0913% | 33 |
| SALAD-Benchattack_enhanced_socioeconomic_harms | Human rights (1) | Higher is better | Human rights (0.737%) | 0.111% | 33 |
| SALAD-Benchbase_human_autonomy_integrity | Human rights (1) | Higher is better | Human rights (0.737%) | 0.111% | 33 |
| SALAD-Benchbase_information_safety_harms | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.369%), Misuse resistance (0.0952%) | 0.0648% | 33 |
| SALAD-Benchbase_malicious_use | Misuse resistance (1) | Higher is better | Misuse resistance (0.19%) | 0.019% | 33 |
| SALAD-Benchbase_misinformation_harms | Truthfulness (1) | Higher is better | Truthfulness (0.347%) | 0.0521% | 33 |
| SALAD-Benchbase_representation_toxicity | Fairness (1) | Higher is better | Fairness (0.913%) | 0.0913% | 33 |
| SALAD-Benchbase_socioeconomic_harms | Human rights (1) | Higher is better | Human rights (0.737%) | 0.111% | 33 |
| SALAD-Benchmcq_human_autonomy_integrity | Human rights (1) | Higher is better | Human rights (0.369%) | 0.0553% | 33 |
| SALAD-Benchmcq_information_safety_harms | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (0.184%), Misuse resistance (0.0476%) | 0.0324% | 33 |
| SALAD-Benchmcq_malicious_use | Misuse resistance (1) | Higher is better | Misuse resistance (0.0952%) | 0.00952% | 33 |
| SALAD-Benchmcq_misinformation_harms | Truthfulness (1) | Higher is better | Truthfulness (0.173%) | 0.026% | 33 |
| SALAD-Benchmcq_representation_toxicity | Fairness (1) | Higher is better | Fairness (0.456%) | 0.0457% | 33 |
| SALAD-Benchmcq_socioeconomic_harms | Human rights (1) | Higher is better | Human rights (0.369%) | 0.0553% | 33 |
| Shelleducation_jsr | Misuse resistance (1) | Lower is better | Misuse resistance (0.62%) | 0.062% | 14 |
| Shellfinance_jsr | Misuse resistance (1) | Lower is better | Misuse resistance (0.62%) | 0.062% | 14 |
| Shellmanagement_jsr | Misuse resistance (1) | Lower is better | Misuse resistance (0.62%) | 0.062% | 14 |
| SimpleQA Verifiedf1_score | Truthfulness (1) | Higher is better | Truthfulness (3.27%) | 0.49% | 13 |
| SM-Benchadversarial | Misuse resistance (1) | Higher is better | Misuse resistance (0.712%) | 0.0712% | 84 |
| SM-Benchambiguous_interpretation | Benign helpfulness (1) | Higher is better | Benign helpfulness (5.19%) | 0.519% | 84 |
| SM-Benchanti_hallucination | Truthfulness (1) | Higher is better | Truthfulness (1.3%) | 0.195% | 84 |
| SM-Bencheq_boundaries | Benign helpfulness (1) | Higher is better | Benign helpfulness (4.15%) | 0.416% | 84 |
| SM-Benchoverfit | Benign helpfulness (1) | Higher is better | Benign helpfulness (5.19%) | 0.519% | 84 |
| Social Welfare Function Benchmarkfairness | Fairness (1) | Higher is better | Fairness (10.4%) | 1.04% | 19 |
| SORRY-Benchavg | Misuse resistance (1) | Lower is better | Misuse resistance (1.9%) | 0.19% | 51 |
| SOSBenchbiology_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SOSBenchchemistry_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SOSBenchmedicine_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SOSBenchpharmacology_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SOSBenchphysics_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SOSBenchpsychology_pvr | Misuse resistance (1) | Lower is better | Misuse resistance (0.298%) | 0.0298% | 23 |
| SpeciesismBenchexplicit_speciesism_scale | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (1.52%) | 0.379% | 7 |
| SpeciesismBenchmorally_wrong_rate | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (4.06%) | 1.01% | 8 |
| SpeciesismBenchspeciesism_recognition_rate | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (1.62%) | 0.406% | 8 |
| SpeciEvalbelief_animal_sentience | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (7.16%) | 1.79% | 117+6 |
| SpeciEvalland_animal_4ns | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (7.16%) | 1.79% | 117+6 |
| SpeciEvalsea_animal_4ns | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (7.16%) | 1.79% | 117+6 |
| SpeciEvalspeciesism | Nonhuman welfare (1) | Lower is better | Nonhuman welfare (7.16%) | 1.79% | 117+6 |
| StereoTales Harmful Associationsbenign_significant_association_score | Fairness (1) | Higher is better | Fairness (8.58%) | 0.858% | 23 |
| SuperCLUE Safetyinstruction_attack | Misuse resistance (1) | Higher is better | Misuse resistance (0.944%) | 0.0944% | 31 |
| SuperCLUE Safetyresponsible_ai | Human rights (0.38), Fairness (0.12), Misuse resistance (0.5) | Higher is better | Human rights (0.822%), Fairness (0.339%), Misuse resistance (0.283%) | 0.186% | 31 |
| SuperCLUE Safetytraditional_safety | Human rights (0.5), Misuse resistance (0.5) | Higher is better | Human rights (1.1%), Misuse resistance (0.283%) | 0.193% | 31 |
| SYCON Benchfalse_presupposition_tof | Truthfulness (1) | Higher is better | Truthfulness (1.13%) | 0.169% | 11 |
| SYCON Benchunethical_queries_tof | Fairness (1) | Higher is better | Fairness (2.97%) | 0.297% | 11 |
| TACbase_welfare_rate | Nonhuman welfare (1) | Higher is better | Nonhuman welfare (24.1%) | 6.02% | 20+67 |
| ThaiSafetyBenchsafety_score | Misuse resistance (1) | Higher is better | Misuse resistance (0.593%) | 0.0593% | 18 |
| The Dictatorship Evaloverall_resistance_rate | Human rights (1) | Higher is better | Human rights (4.3%) | 0.646% | 20 |
| ToolPrivacyBenchprivate_mt_poi | Human rights (0.7), Responsible agency (0.3) | Lower is better | Human rights (2.53%), Responsible agency (0.528%) | 0.458% | 9 |
| ToolPrivacyBenchpublic_mt_poi | Human rights (0.7), Responsible agency (0.3) | Lower is better | Human rights (2.53%), Responsible agency (0.528%) | 0.458% | 9 |
| TrustLLM contemporary collapsed applicationtrustllm | Human rights (0.2), Fairness (0.2), Truthfulness (0.2), Misuse resistance (0.4) | Higher is better | Human rights (0.544%), Fairness (0.674%), Truthfulness (0.256%), Misuse resistance (0.281%) | 0.216% | 8 |
| TukaBenchafri_jbb_cultural_asr | Human rights (0.5), Misuse resistance (0.5) | Lower is better | Human rights (0.884%), Misuse resistance (0.228%) | 0.155% | 6 |
| TukaBenchafri_jbb_harm_asr | Misuse resistance (1) | Lower is better | Misuse resistance (0.381%) | 0.0381% | 6 |
| TukaBenchafrijail_mono_asr | Misuse resistance (1) | Lower is better | Misuse resistance (0.381%) | 0.0381% | 6 |
| UAVBench safety-critical decision recognitionethical_safety_critical_accuracy | Responsible agency (1) | Higher is better | Responsible agency (2.44%) | 0.366% | 27 |
| UK AISI active safety-research compromise continuationactive_compromise_continuation_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (2.4%) | 0.36% | 5 |
| UK AISI cyber-evaluation cheating and prompted self-reportattempted_cheating_trajectory_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.525%) | 0.0787% | 5 |
| UK AISI cyber-evaluation cheating and prompted self-reportspecific_cheating_action_mention_rate_pct | Truthfulness (1) | Higher is better | Truthfulness (0.507%) | 0.076% | 5 |
| Vals AI Cheating Auditbiomystery_bench_cheating_attempt_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.47%) | 0.0704% | 9 |
| Vals AI Cheating Auditswebench_verified_cheating_attempt_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.383%) | 0.0575% | 6 |
| Vals AI Cheating Auditterminal_bench_cheating_shortcut_evidence_rate_pct | Responsible agency (1) | Lower is better | Responsible agency (0.586%) | 0.0878% | 14 |
| Vectara HHEM Factual Consistencyfactual_consistency_rate | Truthfulness (1) | Higher is better | Truthfulness (6.59%) | 0.989% | 94 |
| VETO Misfired Alignmentmisfired_alignment_rate_pct | Fairness (0.65), Benign helpfulness (0.35) | Lower is better | Fairness (7.75%), Benign helpfulness (6.35%) | 1.41% | 25 |
| Vigil Mental Health Safetyoverall_score | Human rights (0.45), Misuse resistance (0.55) | Higher is better | Human rights (3.12%), Misuse resistance (0.984%) | 0.566% | 23 |
| WildClawBench Safety & Alignment (OpenClaw harness)safety_alignment_score_pct | Human rights (0.2), Truthfulness (0.1), Responsible agency (0.7) | Higher is better | Human rights (1.89%), Truthfulness (0.444%), Responsible agency (3.22%) | 0.833% | 24 |
| XSTestsafe_full_compliance_rate | Benign helpfulness (1) | Higher is better | Benign helpfulness (1.57%) | 0.157% | 3 |
| XSTestunsafe_full_refusal_rate | Misuse resistance (1) | Higher is better | Misuse resistance (0.215%) | 0.0215% | 3 |
Values evaluations
Descriptive values evaluations are published separately and receive no safety/ethics component or overall-ranking weight.
UGI Political Values · ValueCompass · Taiwan Sovereignty Benchmark Pro · CAISI CCP narrative alignment · CCPBench political narrative alignment · CCP-aligned censorship behavior · CAIS AI Values — countries · Agent-ValueBench Moral Foundations (MFT08) · Agent-ValueBench HEXACO · Agent-ValueBench Schwartz Basic Values (PVQ40) · The Economist World Values Survey Cultural Map · Moral Trolley Arena · Explore model values